Designing a Data Warehouse
A data warehouse is a place where all the data that is generated by business services is collected and used later on for multiple purposes.
- Data warehouses often contain large amounts of historical data.
- The data within the data warehouse is often used for analysis and reporting.
- The data within a data warehouse is usually derived from a wide range of sources
- Data can be heterogeneous.
In what scenarios would you use a data warehouse?
Let's use an example of a food delivery system.
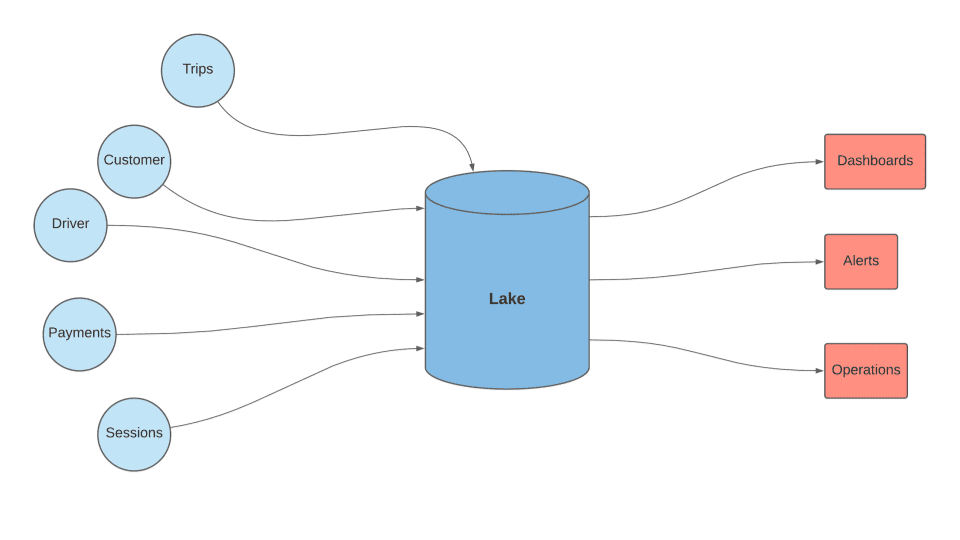
- We have multiple services like Profile, Order, Delivery, etc.
- Each service has its database. Different databases can have different types of database
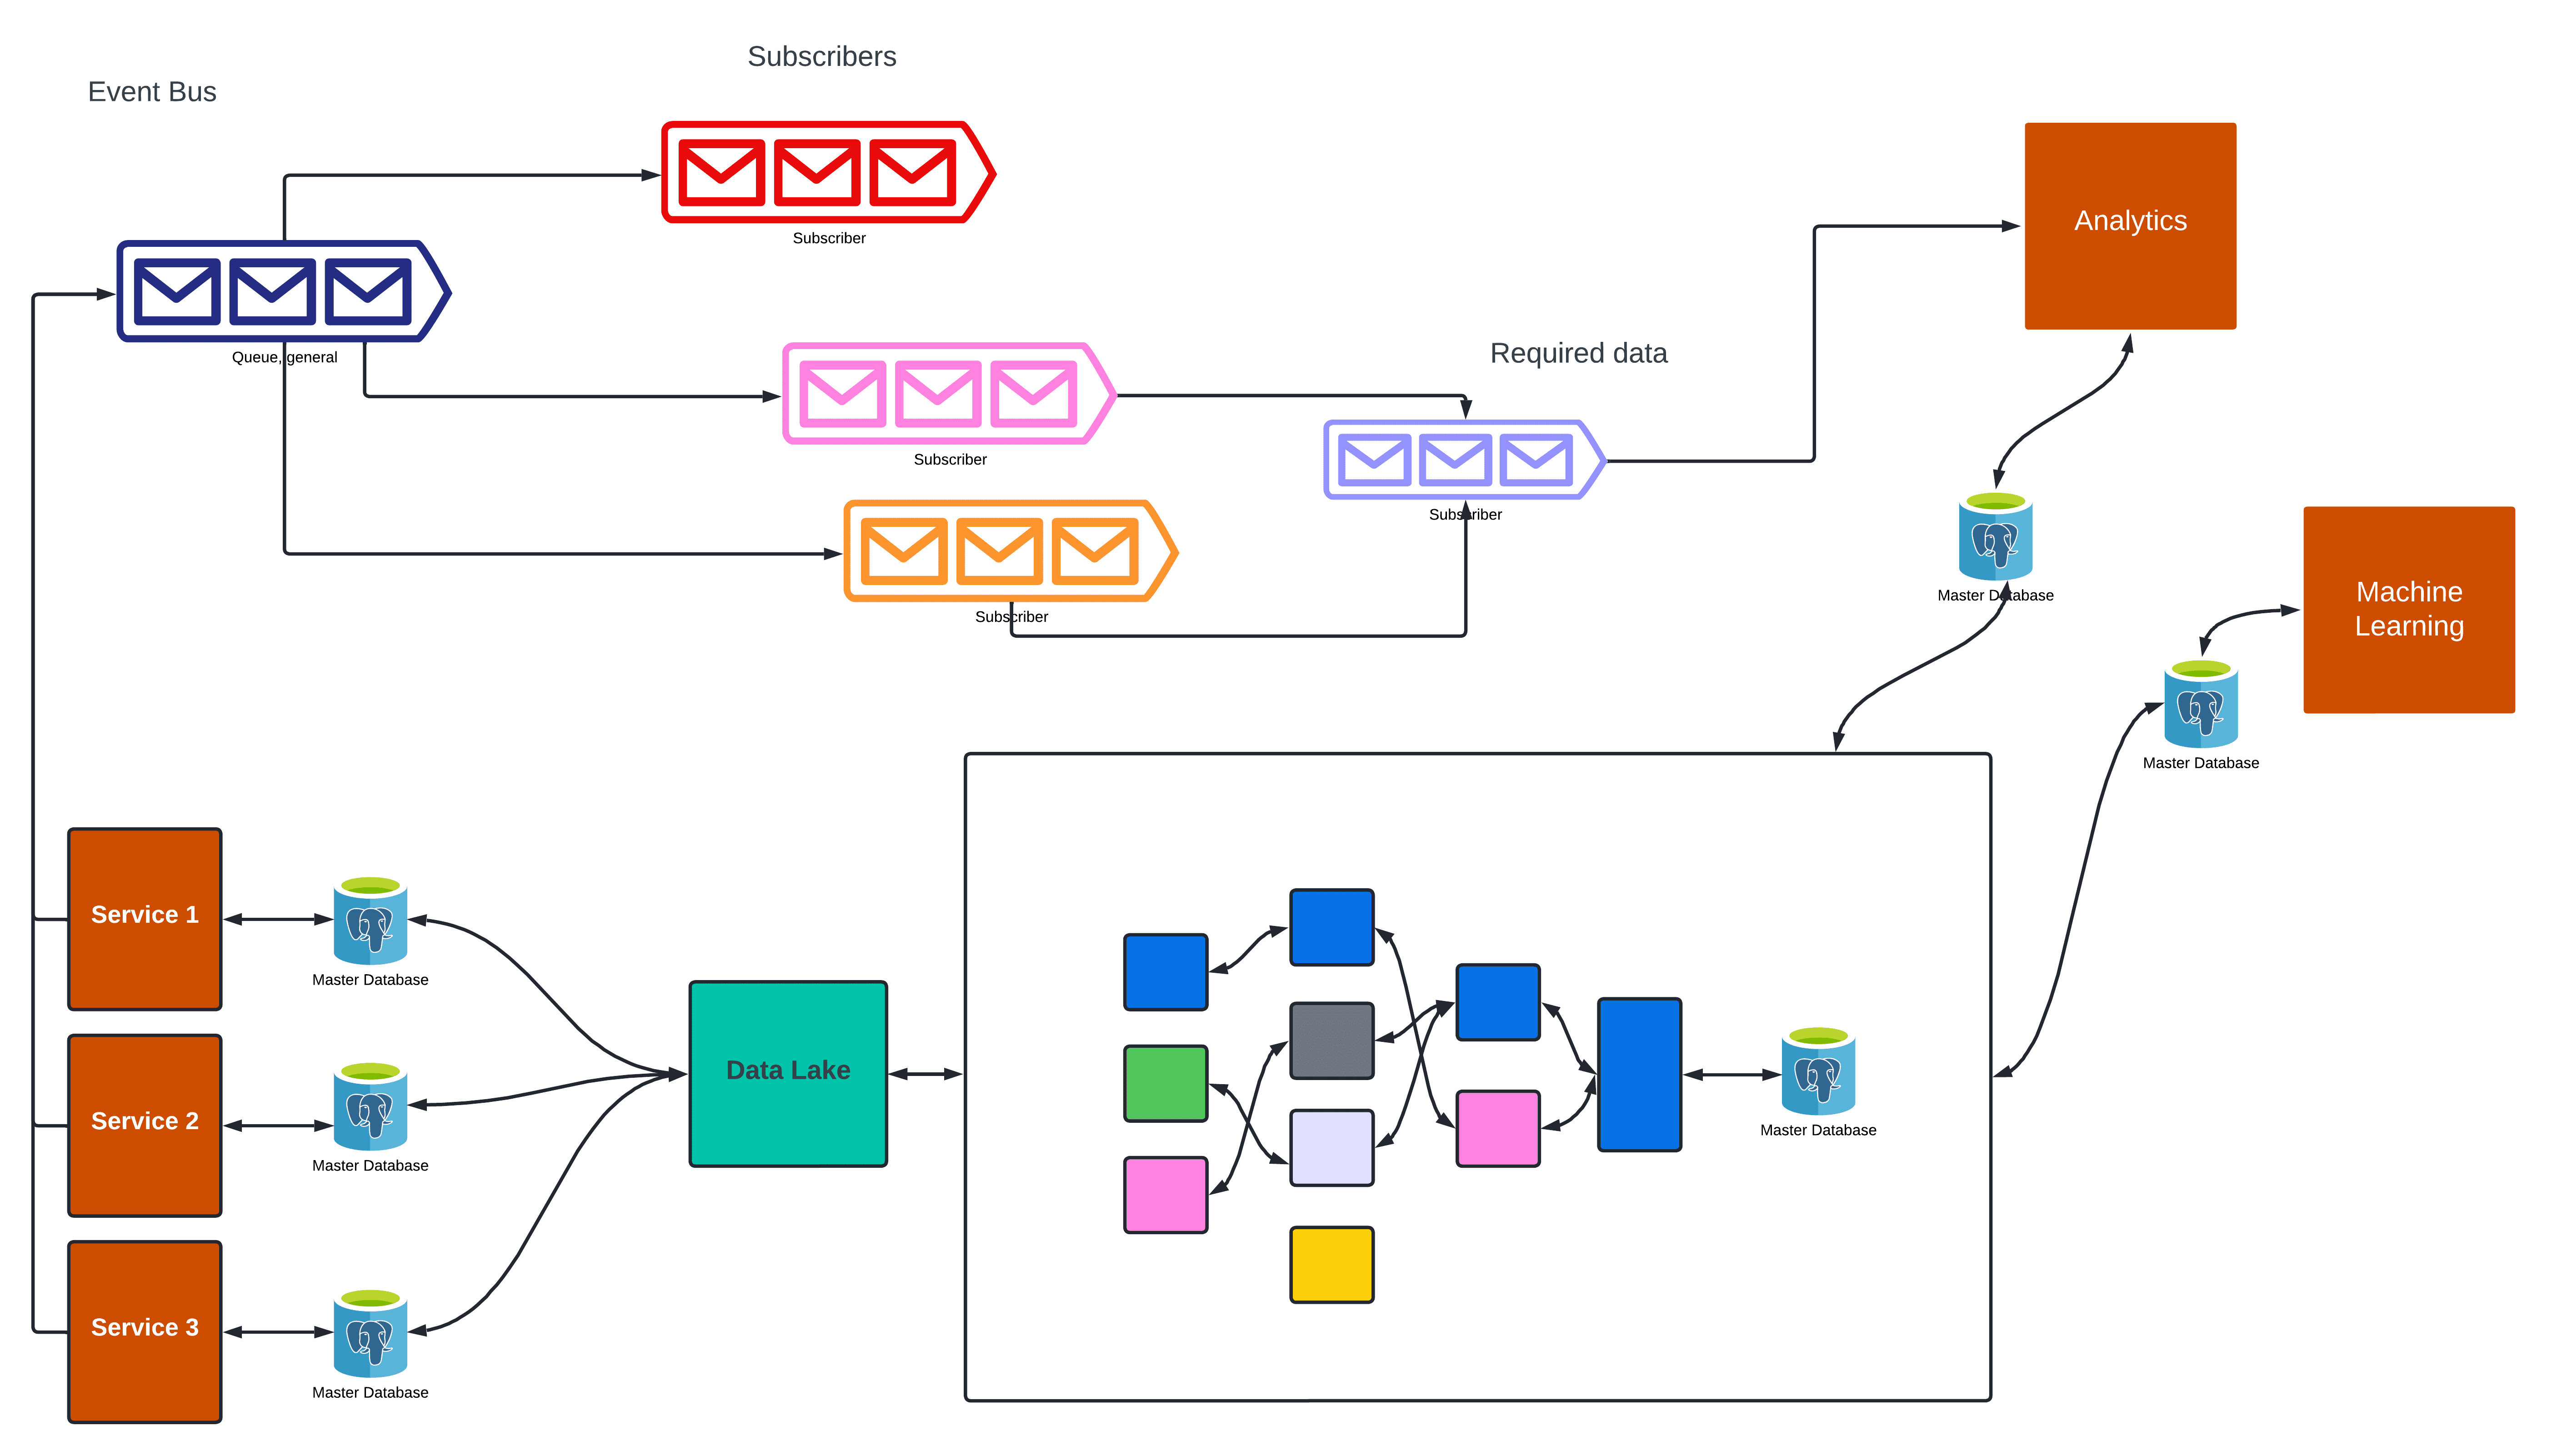
- We collect all the data from the different services and store it in a data lake.
But why can't we query the data from the services directly?
If we directly query the data from the services, every time we need data for analytics or machine learning services we have to query the data from the services, which puts a load on the databases. You are wasting IO resources that could be used by the services.
-
We also need to link the data obtained from different databases in a way that makes sense. To do that, we need to find something that is common across all the databases. In our food delivery system,
delivery_idwill be common across all the databases. -
Once we have the common data, we can perform queries on it.

Few properties of data lakes
-
Since the data is heterogenous it is not easy to make joins on the data. So the data is pulled from these databases in a batch process.
-
Also, the data lake is immutable. We can add entries but cannot update any entries.
-
The data lake should be cheap. We can use a File Storage system like HDFS.
Map Reduce Architecture
Once the data is collected in the data lake, a bunch of nodes will transform the data (These Nodes are services like analytics services or Machine Learning services).
Let's use the same example of a food delivery system.
- We will again use
delivery_idas the common data. - We will partition the data based on the
delivery_id. For example, Node 1 will have the data fordelivery_id1 to 100, Node 2 will have the data fordelivery_id101 to 200, etc. This removes any coupling in the data so they can be processed by each node individually. - The results we get from this layer of nodes are going to push out. The data might be collected or sent to another layer of nodes.
- After the data processing is completed, we will store the data in a dataset and then we can send it to the required services.
This architecture is known as Map-Reduce architecture.

Advantages of using a Map-Reduce Architecture
- It is easy to add new nodes to the system i.e, Horizontal Scaling is easy.
- If any node in any layer fails, we just retry to send the data. Once the failed node recovers it can process the data. There is no Single Point of Failure
- Tasks are broken into stages are run in parallel.
- Since each downstream service wants a different schema of data we can generate this schema by using the same data lake and hardware giving different outputs. Different nodes can process the data in different ways. So by using a different combination of nodes we can generate different outputs. This makes this architecture cost-effective because we are re-using different nodes and flexible.
Note
Data Flows from Data Lake to Services. So data lake is upstream while the services are downstream. This process is known as ETL architecture.
- E for "Extract". Because we are extracting the data from the data lake.
- T for "Transform". Because we are transforming the data.
- L for "Load". Because we are loading the data into the services.

Making Engineering Optimizations
Suppose in our architecture, Node 1 is sending data to Node 2. Now if Node 2 crashes, Node 1 will not be able to do other tasks until Node 2 recovers. So our first issue is Dependencies
To get rid of this we need to ask
- When
Node 1processes the data will it push the data toNode 2? - Or
Node 2pull the data?
Well, we can use both. We can put a database in between nodes. This table acts as an intermediate table. When Node 1 processes the data it will push the data to the intermediate table. Then Node 2 can pull the data from the intermediate table whenever it is ready.
Now even if Node 2 crashes Node 1 can push the data and perform other tasks. It does not have to wait for Node 2 to recover. Or we can say we decoupled the system.
Through health checks, we make sure that the nodes are working fine. If a node is in bad health we can just replace the node. This works because nodes are stateless i.e, their output completely depends on the input. So we can resend the data from the intermmediate table to the new node. This makes our system more fault tolerant
Another optimizaion we can run a process in regular intervals (cron jobs) which will clean up the intermediate table.
Getting Real-Time Data from Data Lake
Data lake is heterogeneous. Processing data takes time. So instead we ask the services push event to an event bus. Now there are multiple subscribers consuming a certain type of data. Services can then combine events from two or more bus to get the required data. Once the data is ready, sevices can pull the required data.
This is known as Streaming architecture.
Streaming architecture provides data in real-time which is an huge advantage over ETL architecture. However, we don't use it everywhere because -
- Streaming architecture does not persist data. Event bus pull the events and then push it. On the other hand Data Lake is persistent.
- ETL Architecture can perform more complex operations.
- Streaming architecture is more focused on availability compared to consistency. So there can be loss of data. All the data from the database will be pulled by the data lake so there will be perfect consistency.
In practice we use both streaming and ETL architecture. This is known as Lambda architecture