
Have you noticed a small icon on the right of LinkedIn profiles?
It tells you how closely you are related to a user (1st, 2nd or 3rd-degree connection).

1. Linkedin Connections
These distances are calculated using graph algorithms. Specifically, LinkedIn uses Bi-directional BFS.
This is a two-way algorithm where a search starts from the source and destination and is terminated midway. The total distance traveled from source+destination is the degree of the connection.
But at scale, this solution brings challenges. Let's limit ourselves to finding 3rd-degree connections:
- Every query needs a graph traversal on our social network.
- A naive BFS would take O(n^3) for search. A bi-directional BFS needs O(n^2) for searching users + O(n^2) for merging results.
- To avoid performing these queries repeatedly, we cache the second-degree connections of users. This saves up on the first O(n^2) factor for subsequent queries.
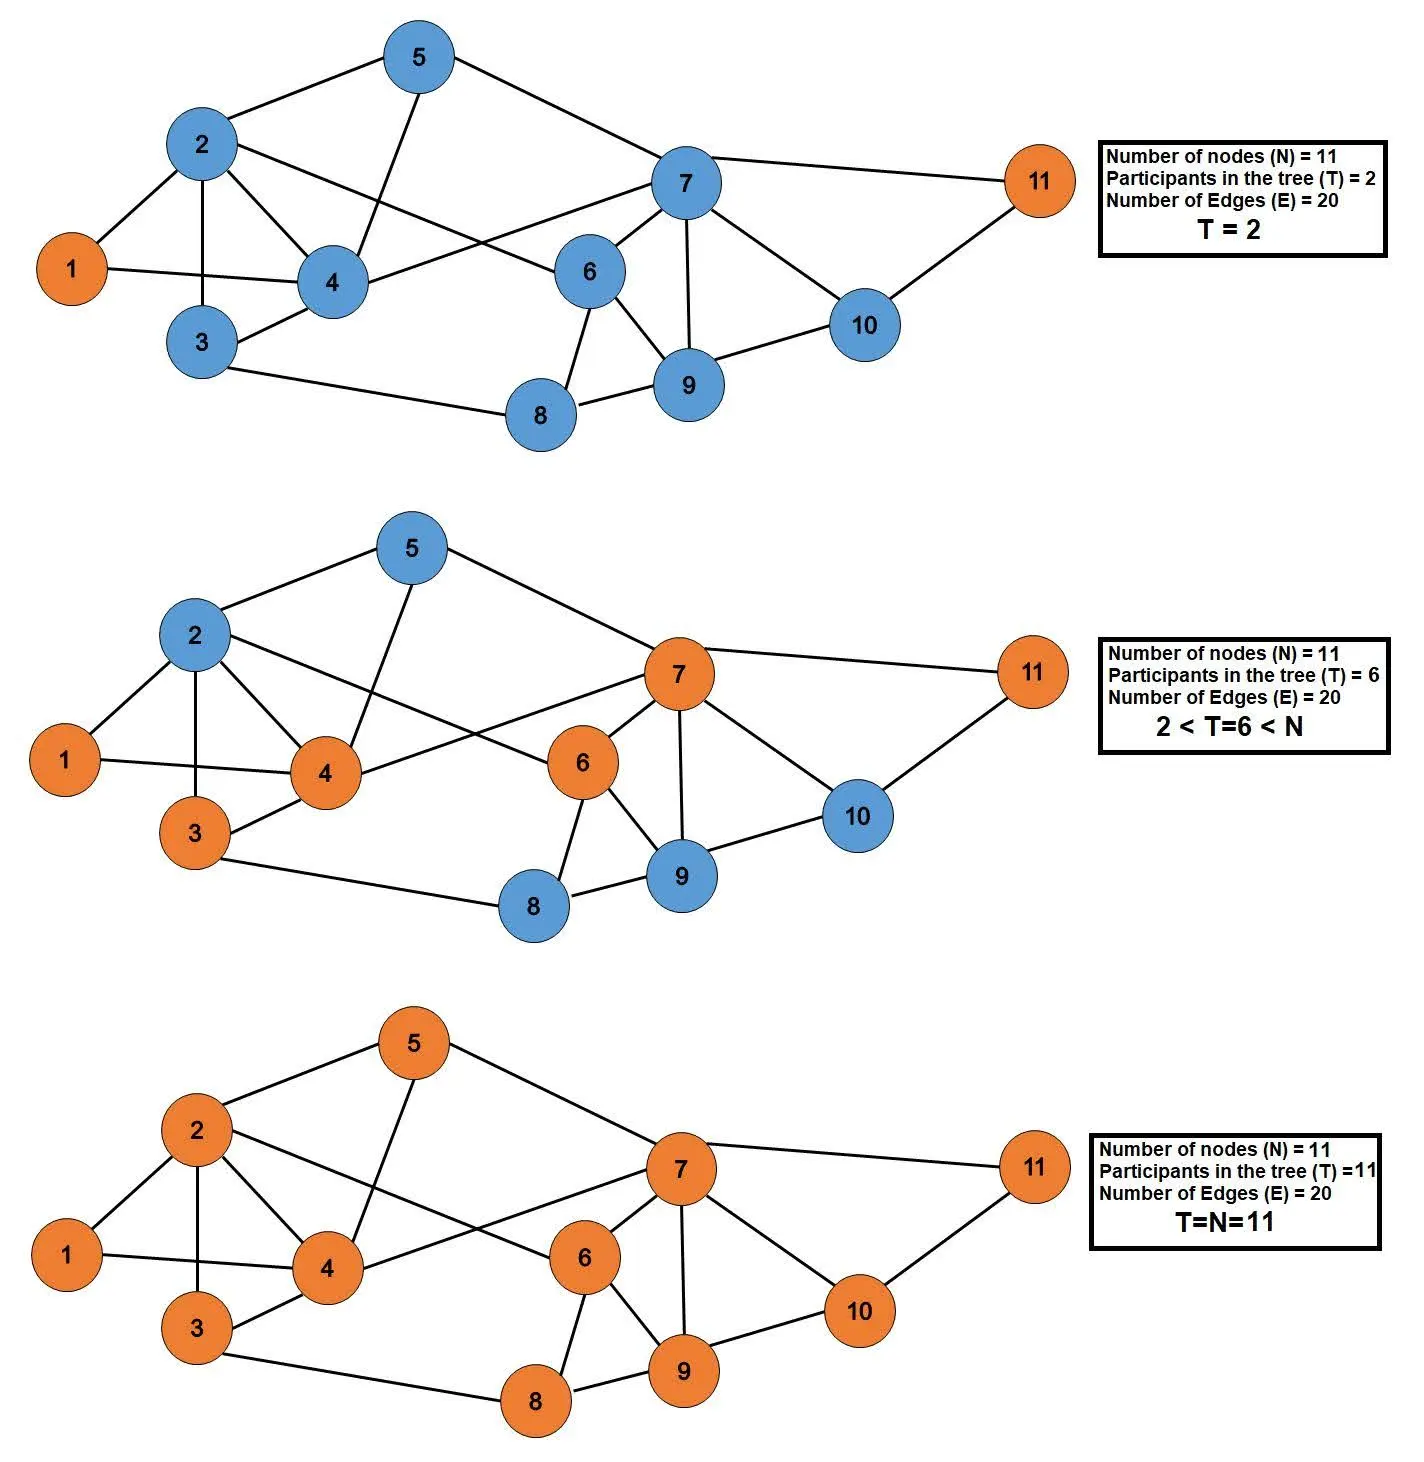
2. Bi-directional BFS algorithm
Great, but how do we store all this data in a single cache?
Well, we can't. LinkedIn is forced to scale out, with multiple cache nodes storing second-degree connections. User-Connection data is sharded into caches according to user_id.
But what if a machine crashes? All queries to the shards hosted by that machine will fail.
To avoid this, we replicate shards into different machines. Even if one of the machines fails, the shard can be found on another machine.
And here we meet our main villain: High Latency.
We don't want to hit all the machines with our shards. We want to hit the SMALLEST possible number of machines, that contain all our shards.
For the mathematically inclined, this is a set-cover problem. LinkedIn uses a modified greedy version of the problem to reduce its compute costs in half!
The basic idea is to find machines that host most of the users who are your 2nd-degree connections and avoid those that have few 2nd-degree connections.
Less effort, more work done!
Here is the paper: Link
Phew! I hope you enjoyed it :D