
You notice a problem. The following image isn't loading.
 1. Don't worry, your internet is fine. This is a sample "failing" image.
How would an engineer debug this issue? They would dig through logs for the error: "image not found".
2. Requests trigger multiple systems in the backend, with distributed logs.
In small companies, this is an easy process. An engineer logs into an EC2 instance, fires a grep query, and scrolls through the results.
At Google's scale, this becomes impossible. More than one PetaByte of request data is generated at Google every day. Storing and querying request logs is slow, expensive, and an IO bottleneck.
Google had two main choices here:
1. Persist only failed logs
Since most debugging happens with failed requests, we may persist only failed request logs. This is hard to do in a distributed system, as requests hit multiple systems.
Once a request fails in one system, all related systems will have to be notified of the failure. These systems will then individually persist their logs for this request.
The coordination requirement means lots of IO and memory use. Google decided to avoid this approach.
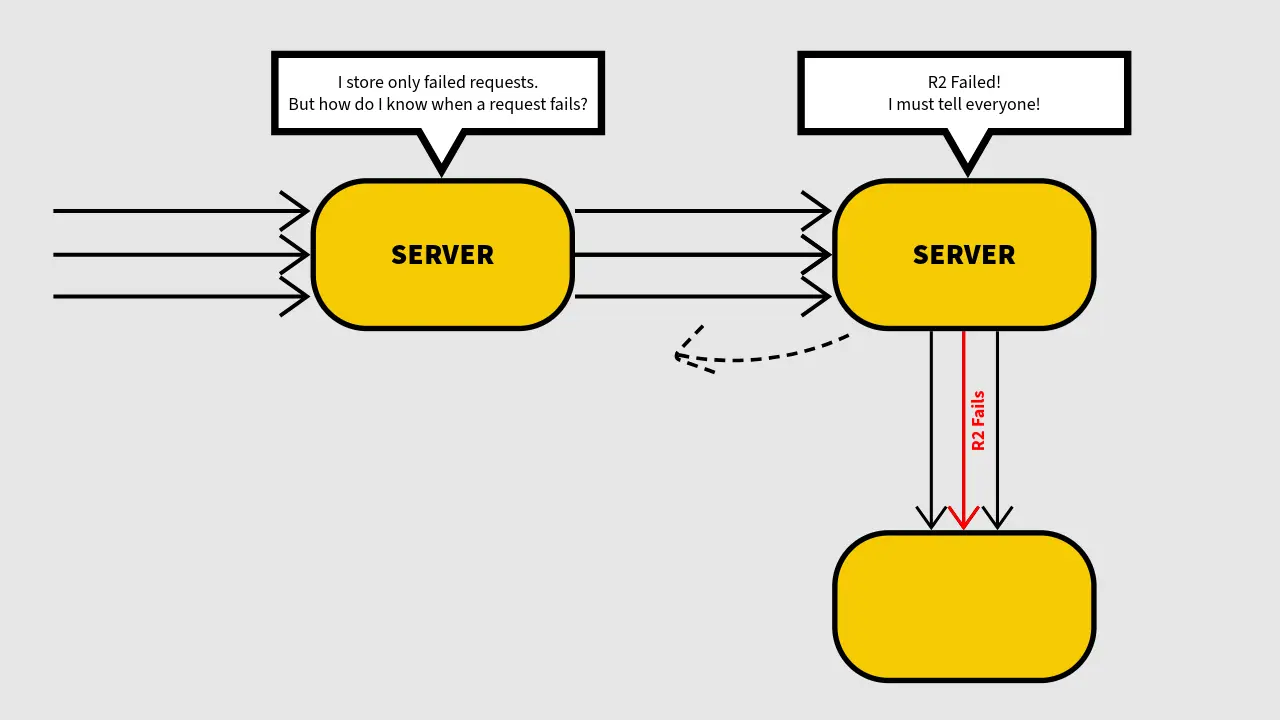 3. Tracing with coordination is complex and expensive.
2. Random Sampling
Storing all logs is infeasible. Instead, we randomly pick requests and persist their logs in their entirety.
For example, the server failed to return the image above. The server must have logged this failure. An engineer needs one sample request to debug it.
Since many requests fail to fetch an image, we persist a few sample traces.
And since request failure is difficult to predict, these samples are chosen randomly.
At Google's scale, the sampling rate is set to 1 : 1024. That means for every 1024 requests, one request trace is persisted in the system.
The sampling rate for dev environments is understandably higher. Since the volume of requests is lower, requests are sampled at a rate of 1 : 100.
The system that stores these traces is called Dapper. Thousands of services connect to this system over the network, using Dapper client libraries.
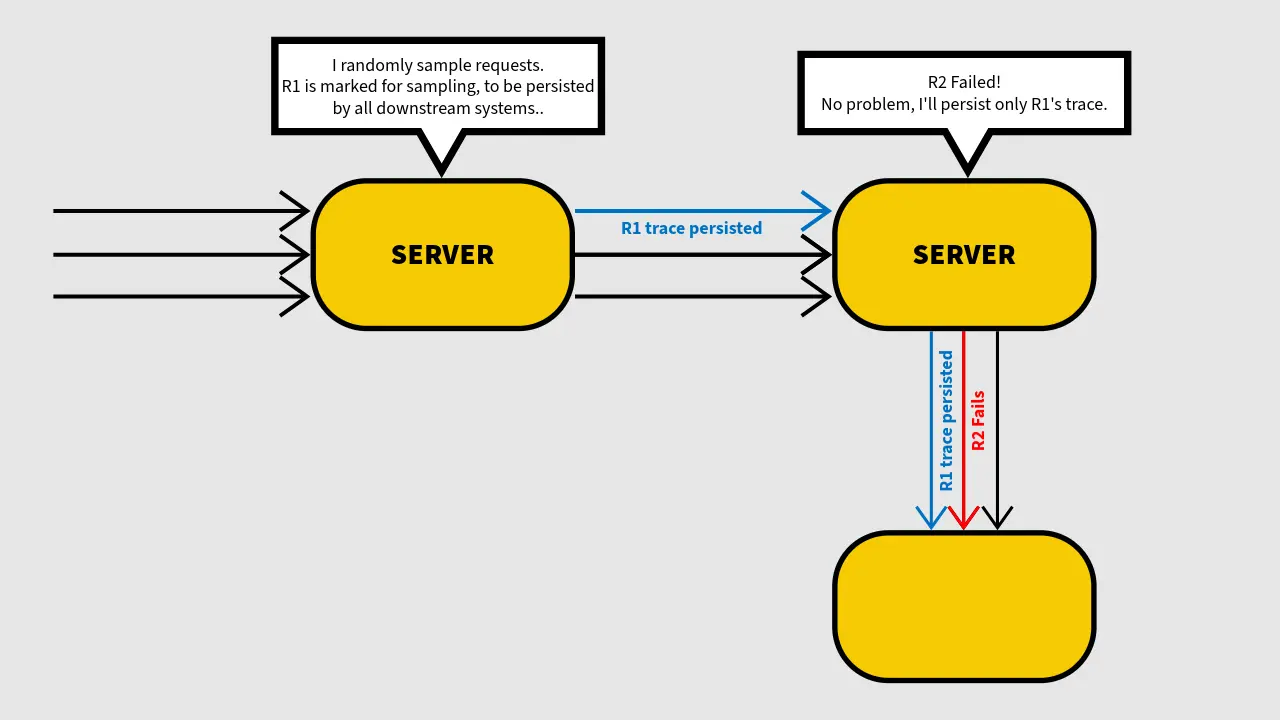 4. Sampling is simple and cheaper.
Performance Impact
Dapper's impact on the performance of Google's latency is -0.20%.
Wait, does Dapper make a system faster?
In reality, Dapper's impact on a system is low enough to be within the margin of error. Hence the imaginary speedup.
| Sampling frequency | Change in avg. latency |
|---|---|
| 1/1 | 16.3% |
| 1/2 | 9.40% |
| 1/4 | 6.38% |
| 1/8 | 4.12% |
| 1/16 | 2.12% |
| 1/1024 | −0.20% |
Final thoughts
Dapper is an engineering marvel. It lets engineers at Google trace a request through multiple systems.
The original paper has been cited over 800 times, and is worth a read!
If you would like to know more about distributed systems in the real world, check out the System Design Course at InterviewReady.
Cheers!