
Git scales to over 500 million repositories and is used by over 20 million software developers.
It offers unparalleled speed, reliability, and ease of use.
But what allows Git to manage massive amounts of data at scale? In this blog, we peel open the layers of algorithms and data structures powering the silent behemoth.
1. FILES
How does Git store files?
Fundamentally, Git is an object database. It provides a version control system for software developers to update, share, and manage code.
Here is how Git stores files.
- A user creates or updates a file.
- The user then registers the file on Git using 'git add'.
- Git hashes the file's contents to generate a unique string, say X.
- The first two characters of X determine the object's parent directory.
- The rest of the characters in X form the address of this object.
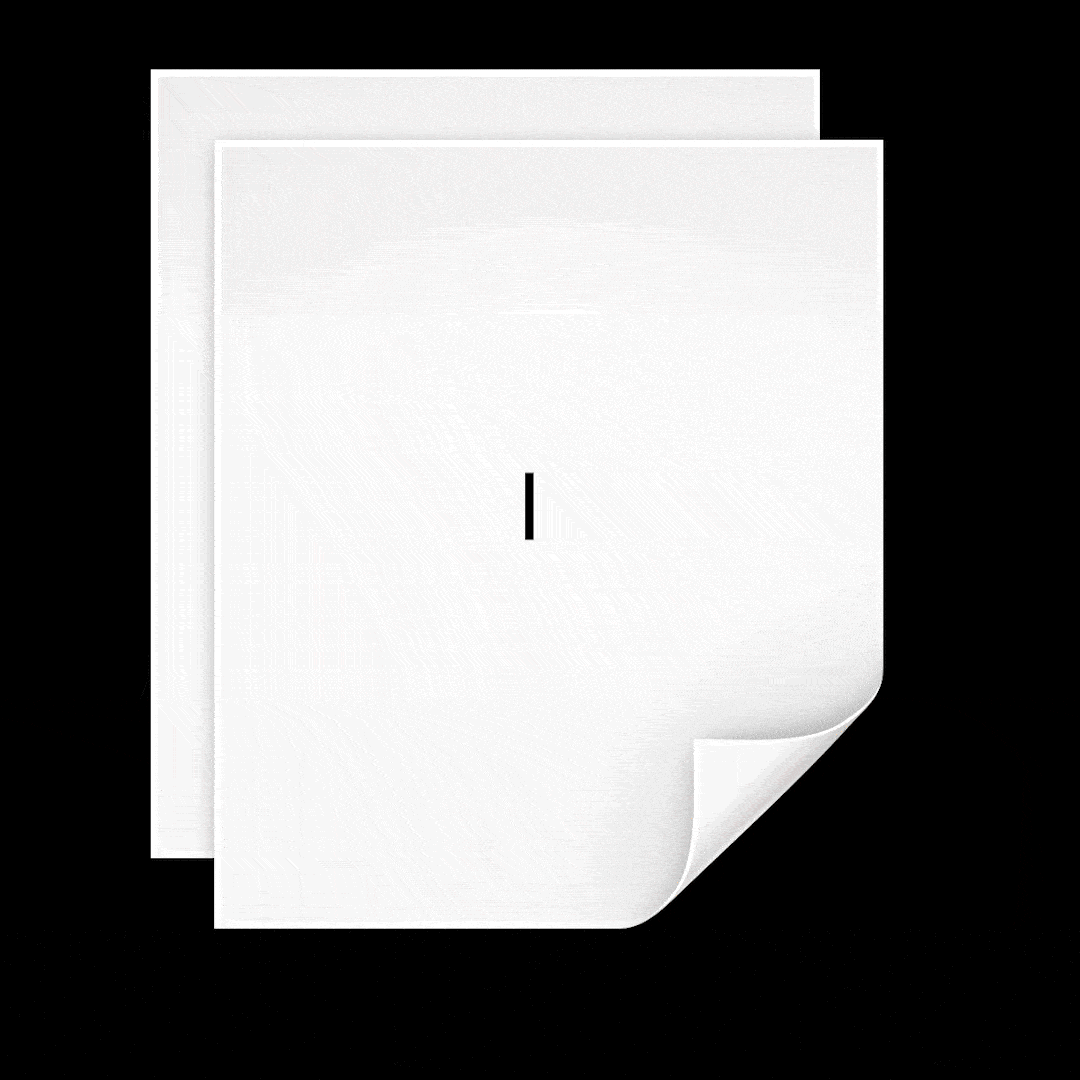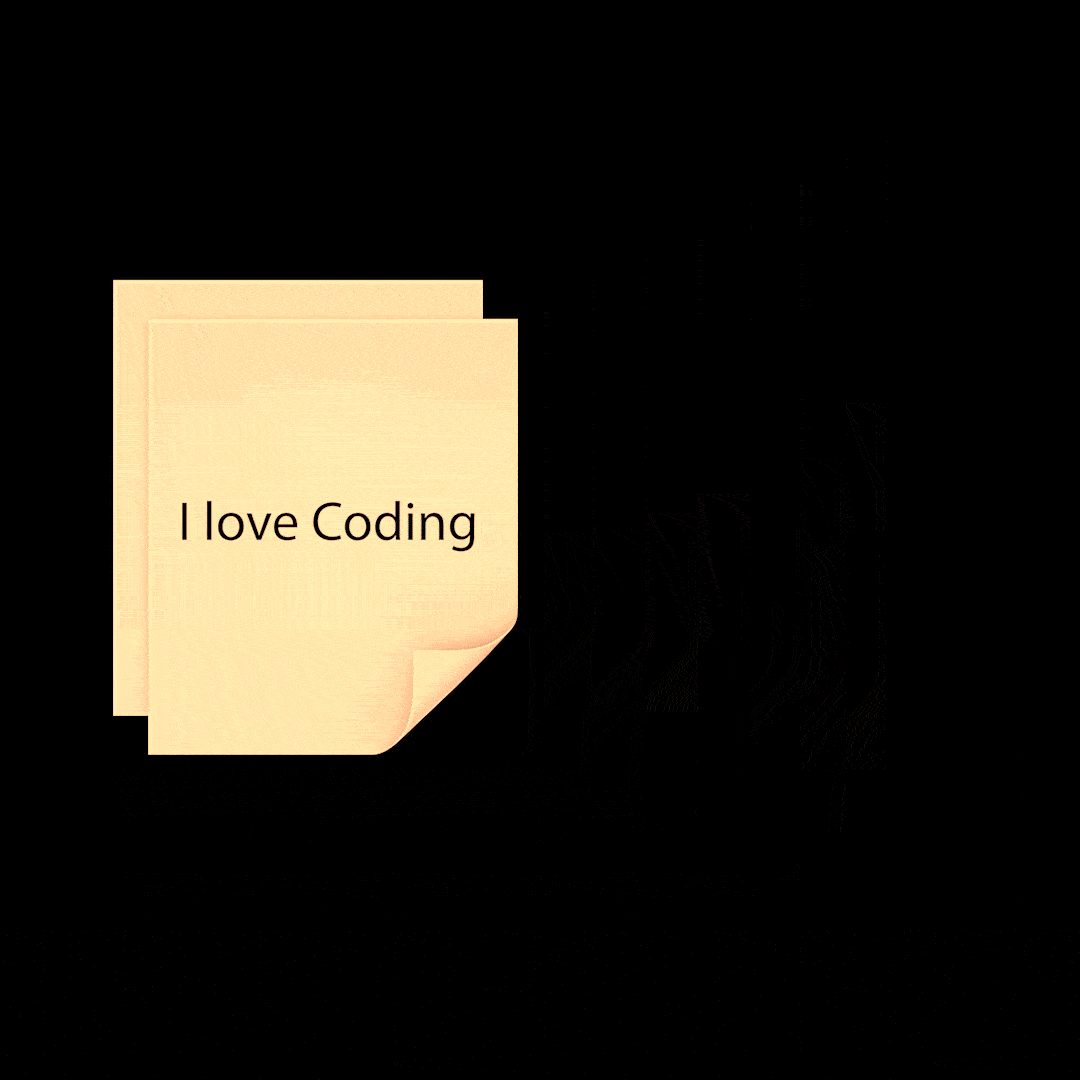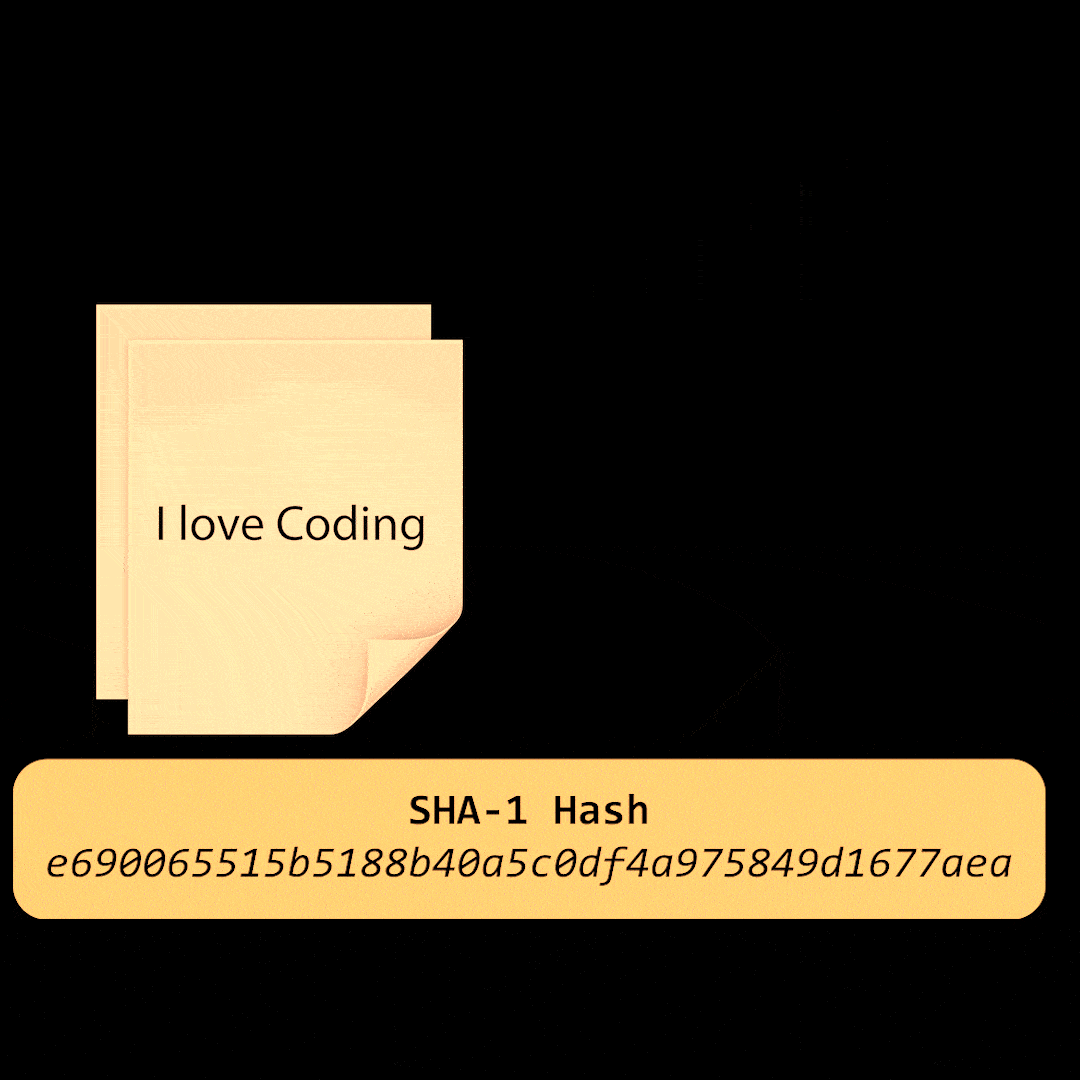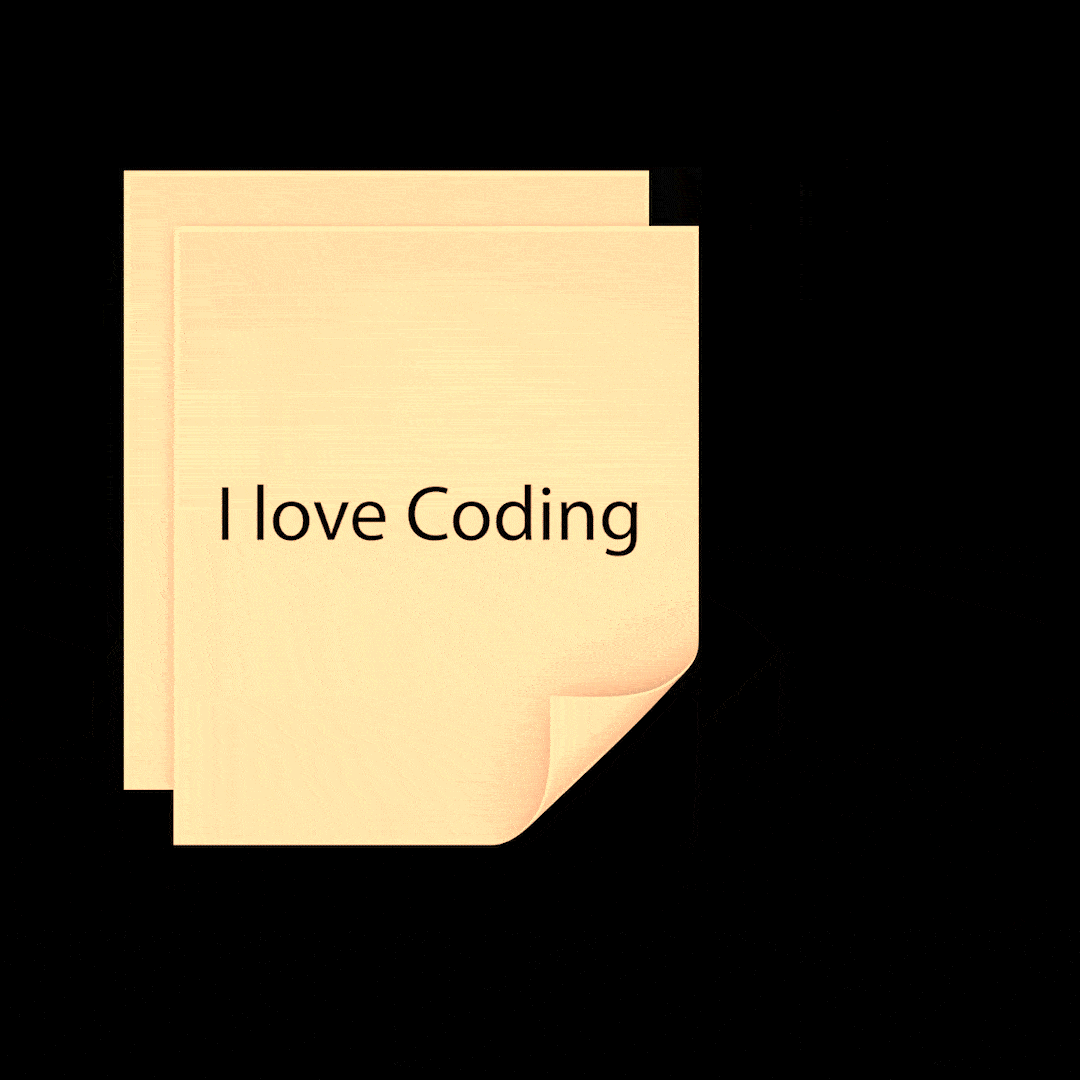
1. Git Object creation on file add
The algorithm splits files into random directories. Since SHA-1 is uniformly random, we are effectively storing our files in a highly-performant unordered hashmap.
Furthermore, to optimize space and network transfers, Git compresses files using GZIP.
2. DIRECTORIES
How are files structured in Git?
Taking inspiration from Unix directories, Git has an object type called Tree. These objects store lists of files with their metadata like ID, name, and location.
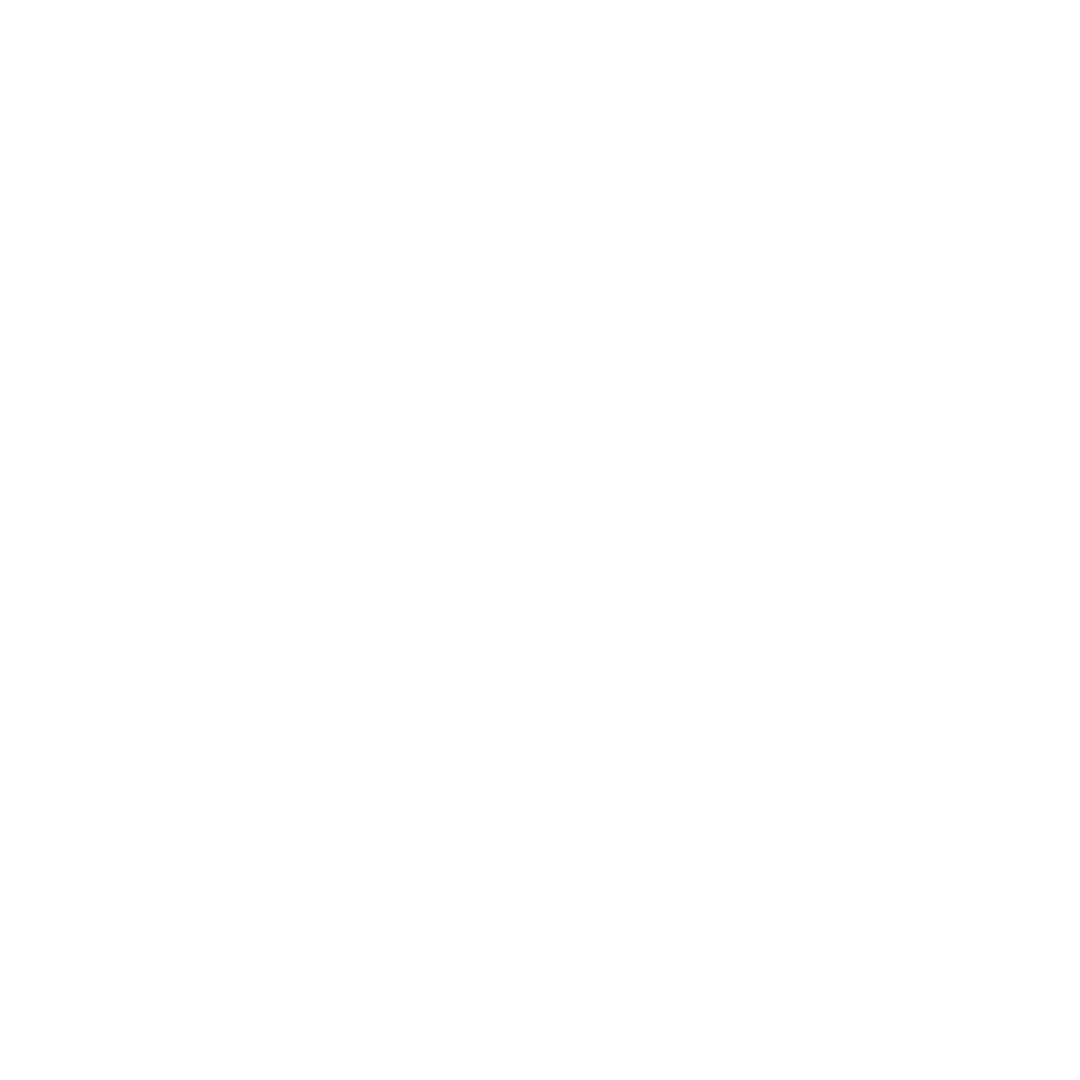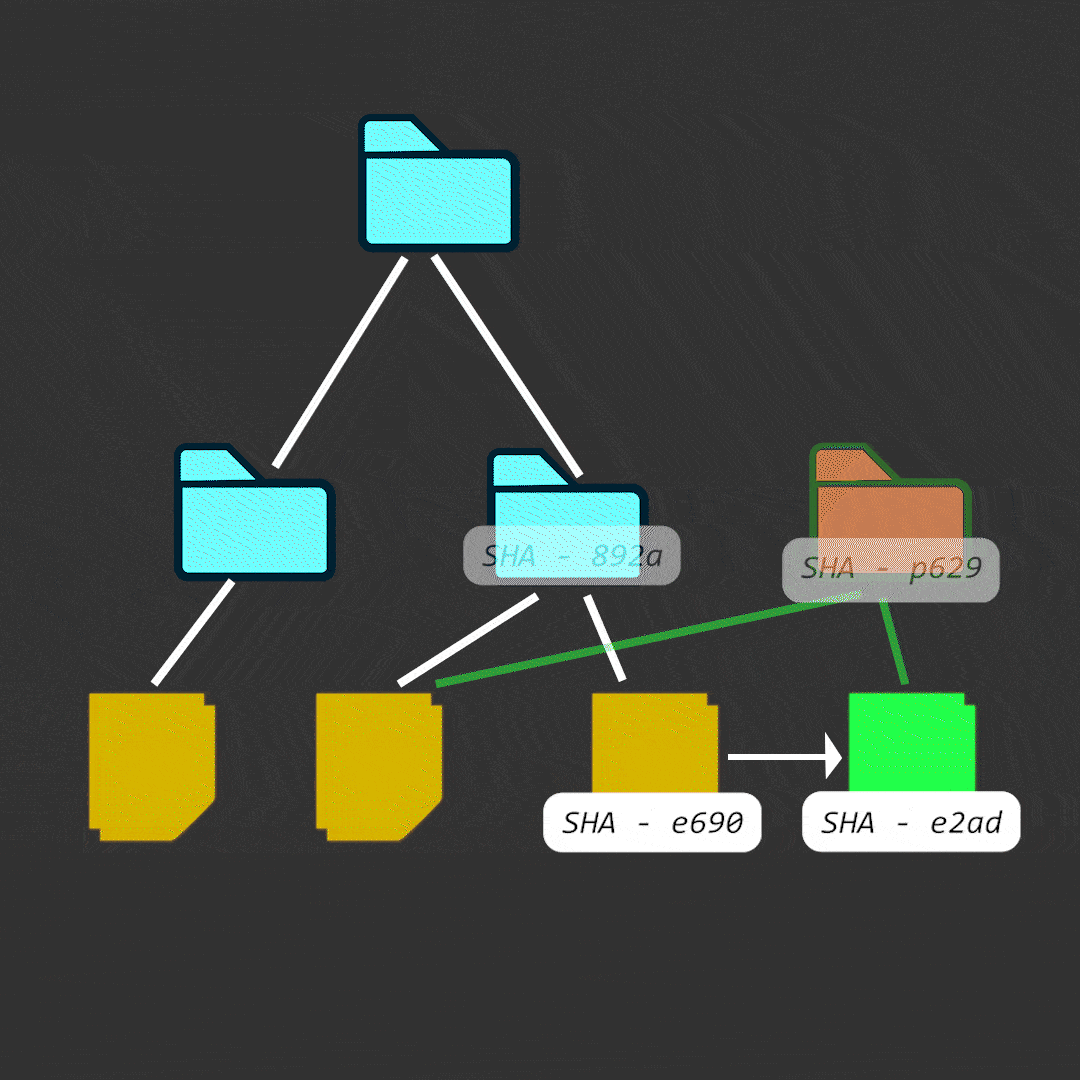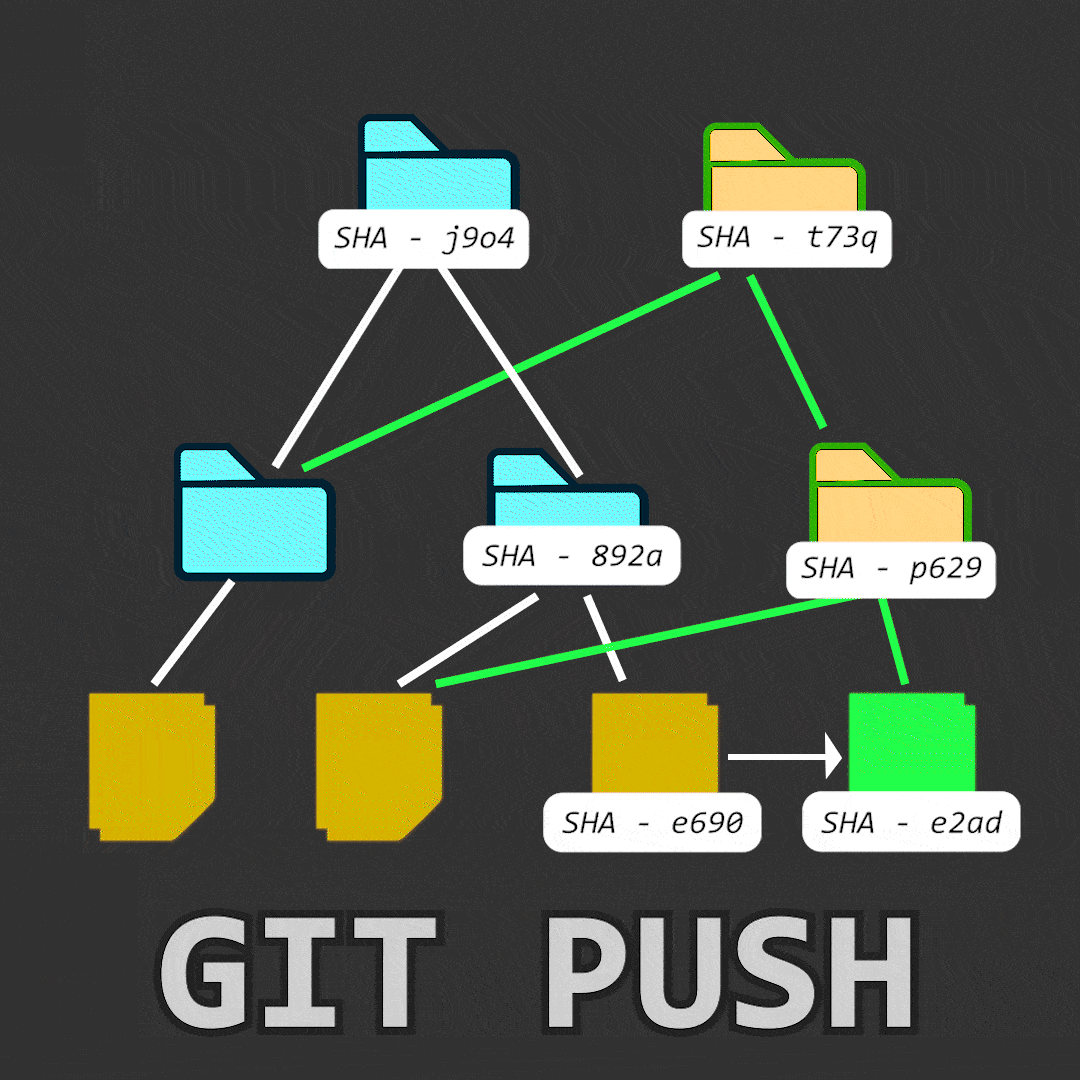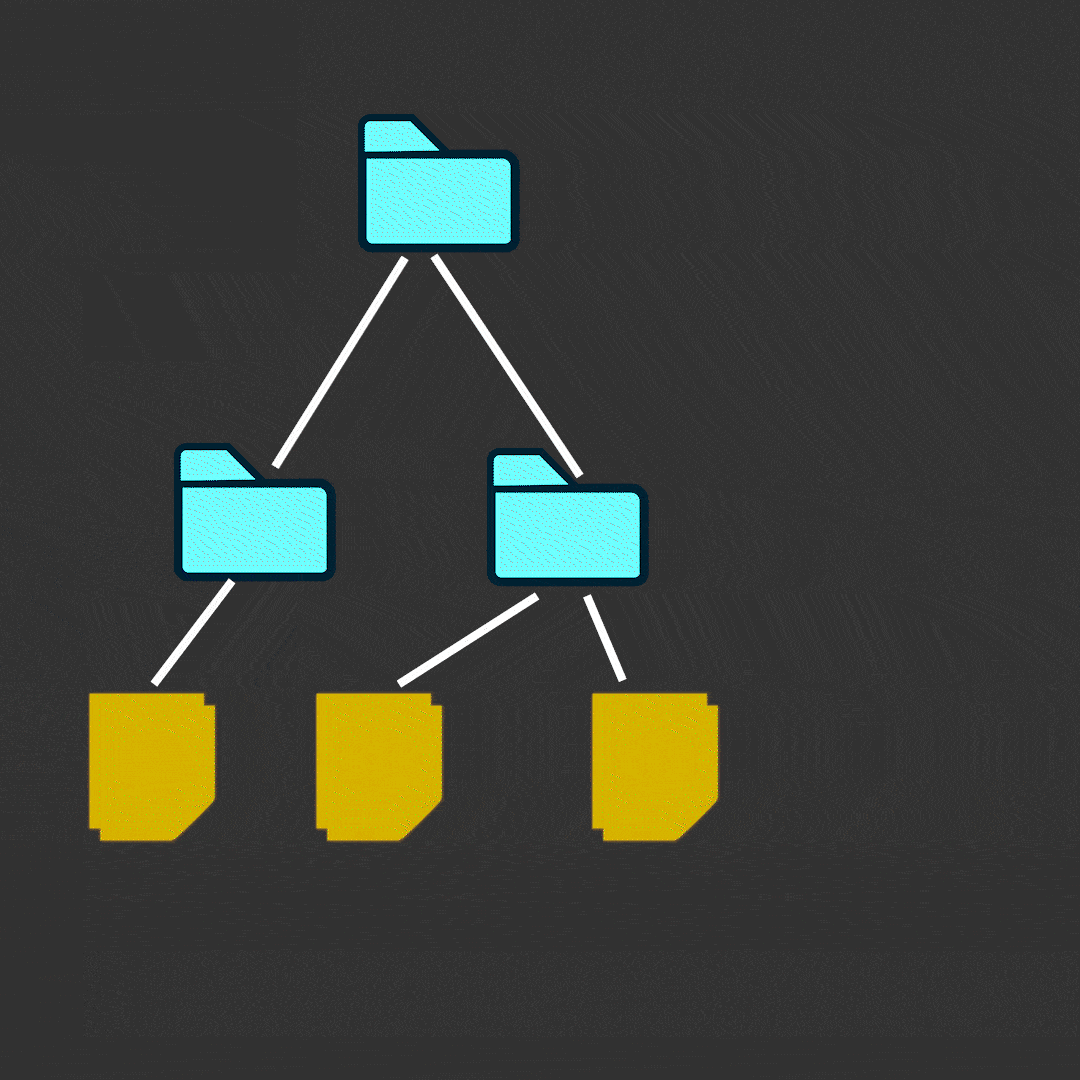
The tree objects merge recursively to the root folder of Git, allowing efficient traversal and comparison of files under them. More on this later.
3. VERSION HISTORY
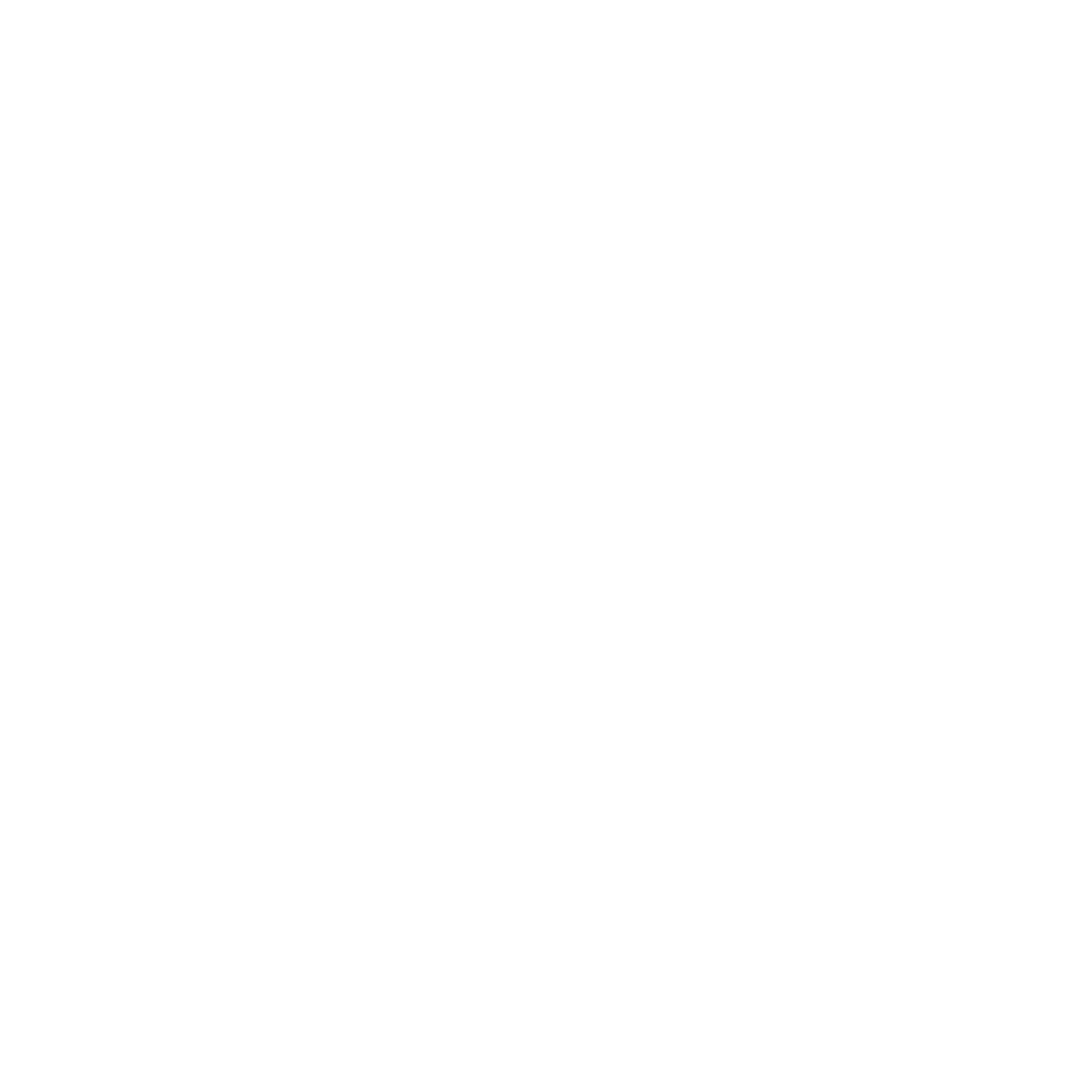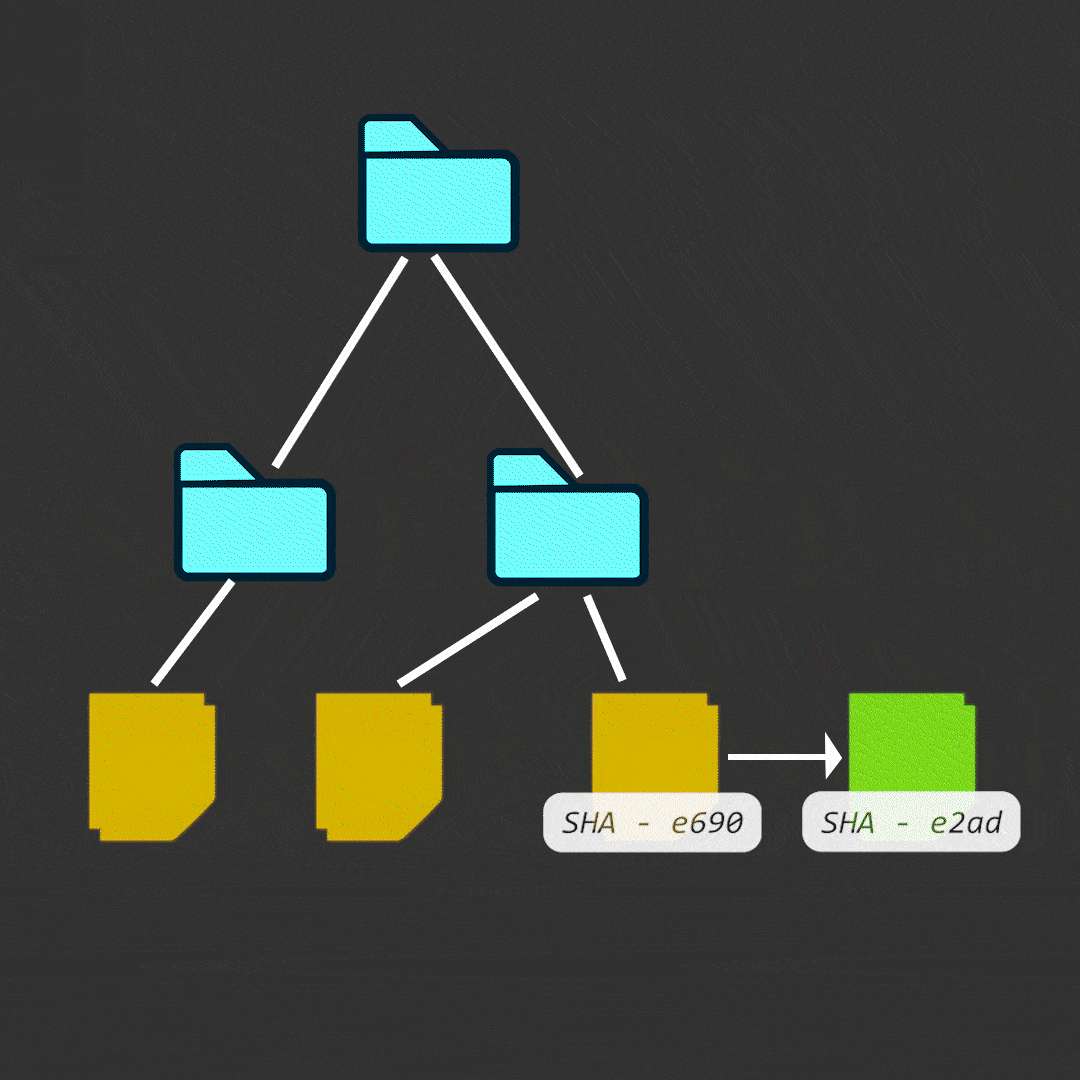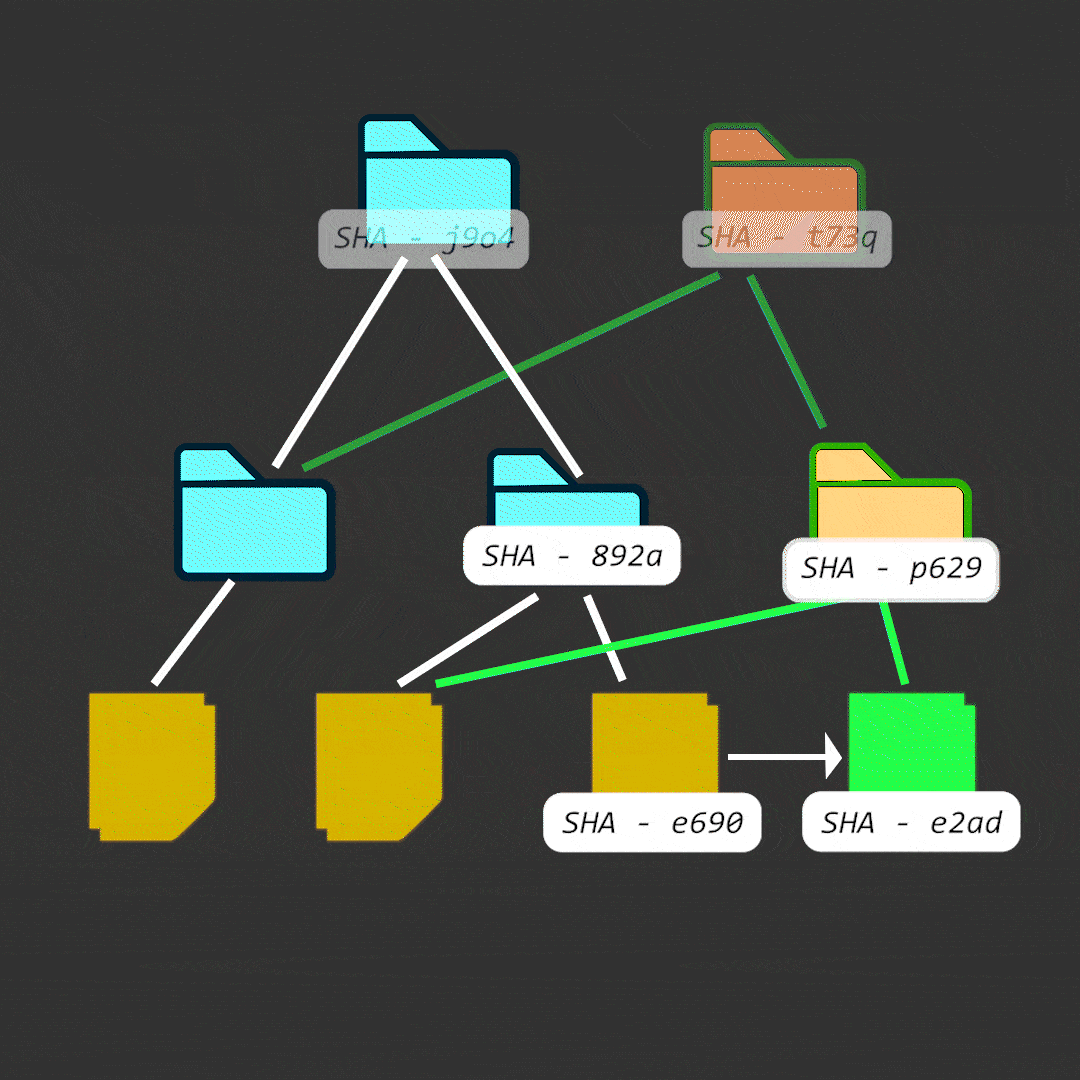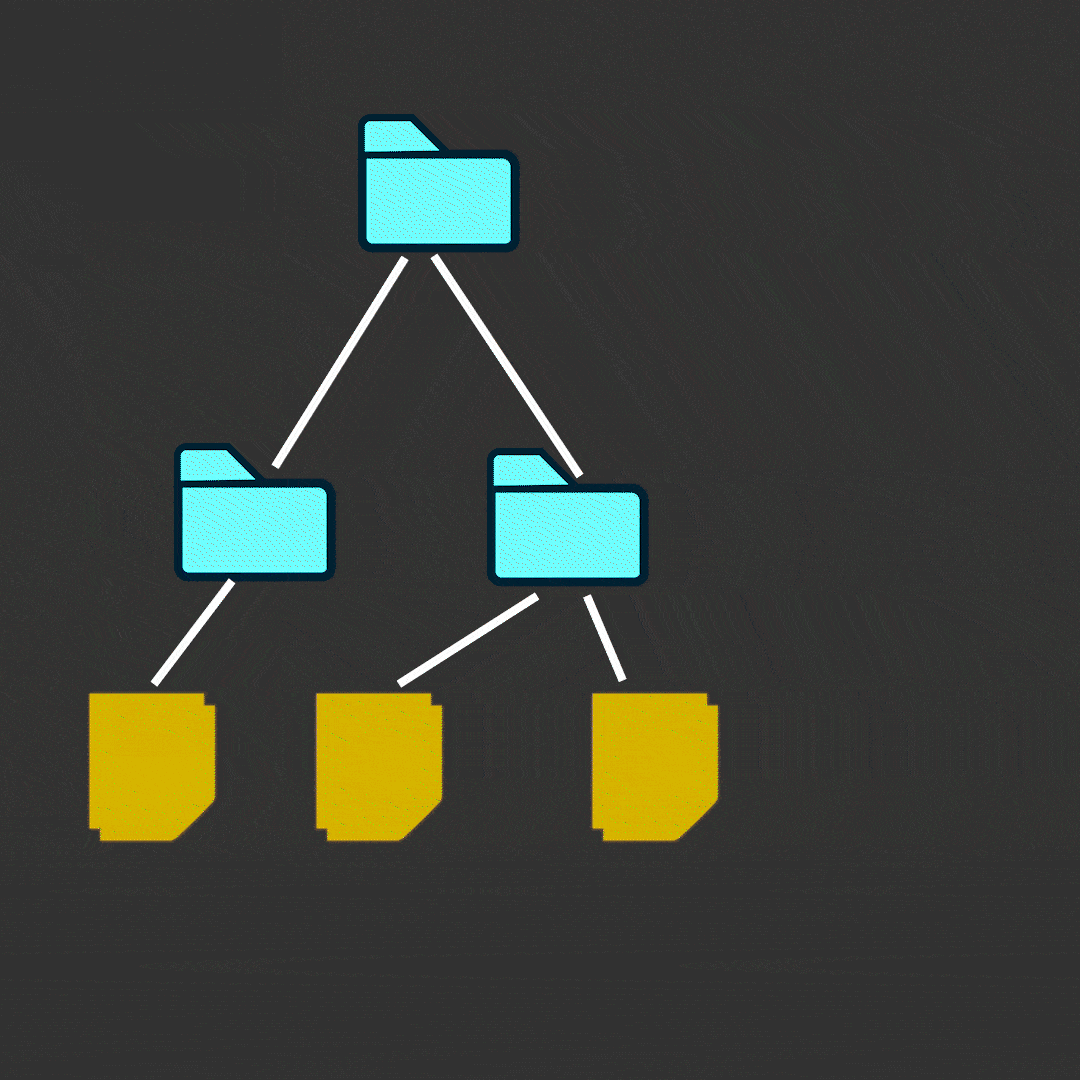
Let's say we update a file by changing a variable name.
To maintain version history, Git will store both old and new versions of this file in different locations, determined by their SHA-1 hash. All other objects are unchanged, including trees.
This allows Git to change just the necessary subtree of a file system and simplifies the version history by making objects immutable.
2. Directory Structure with Immutable Operations
But wait, this means every file change would create a new file!
This naive algorithm would result in many copies of a single file throughout history, eating into disk space and slowing down network transfers.
How can we compress files across their version history?
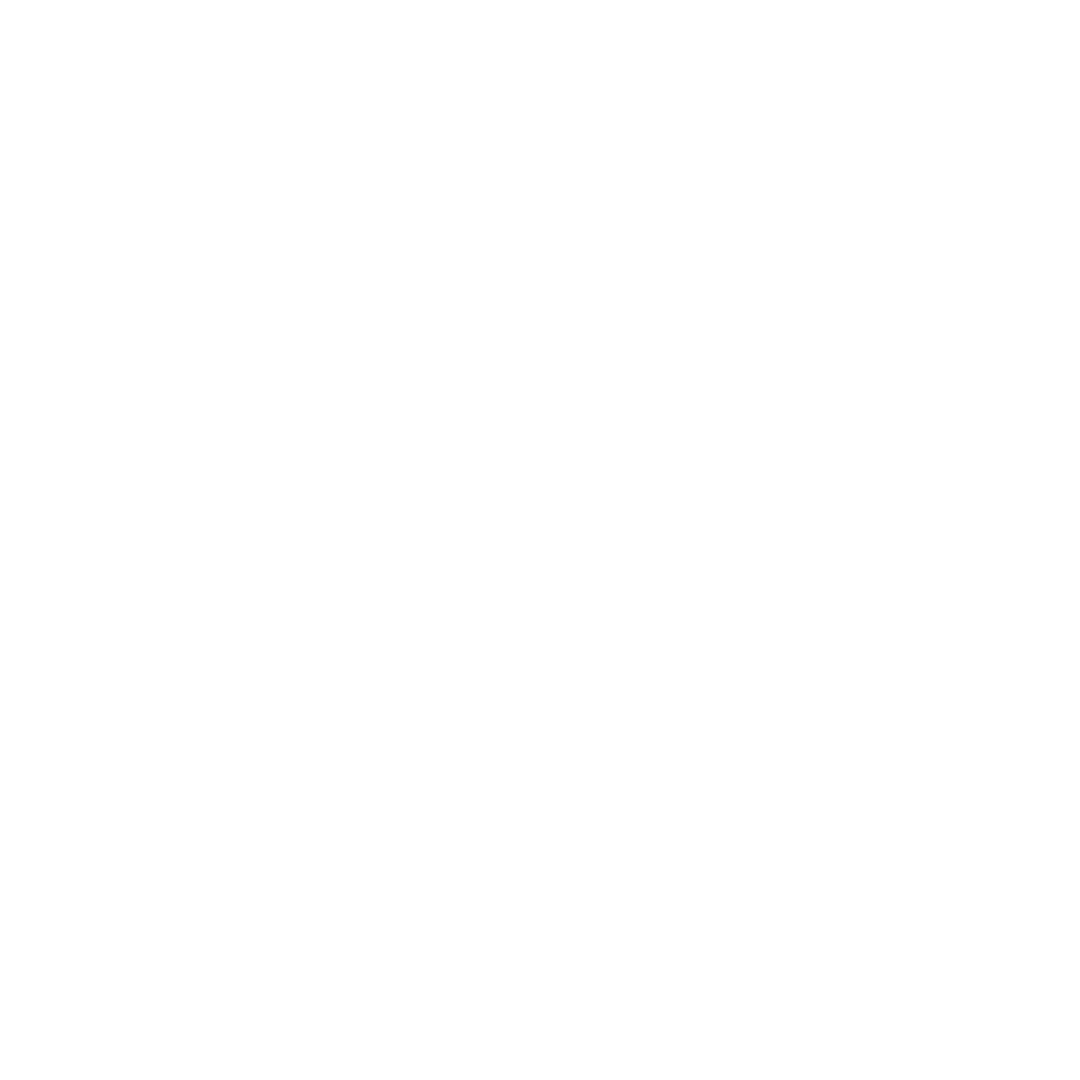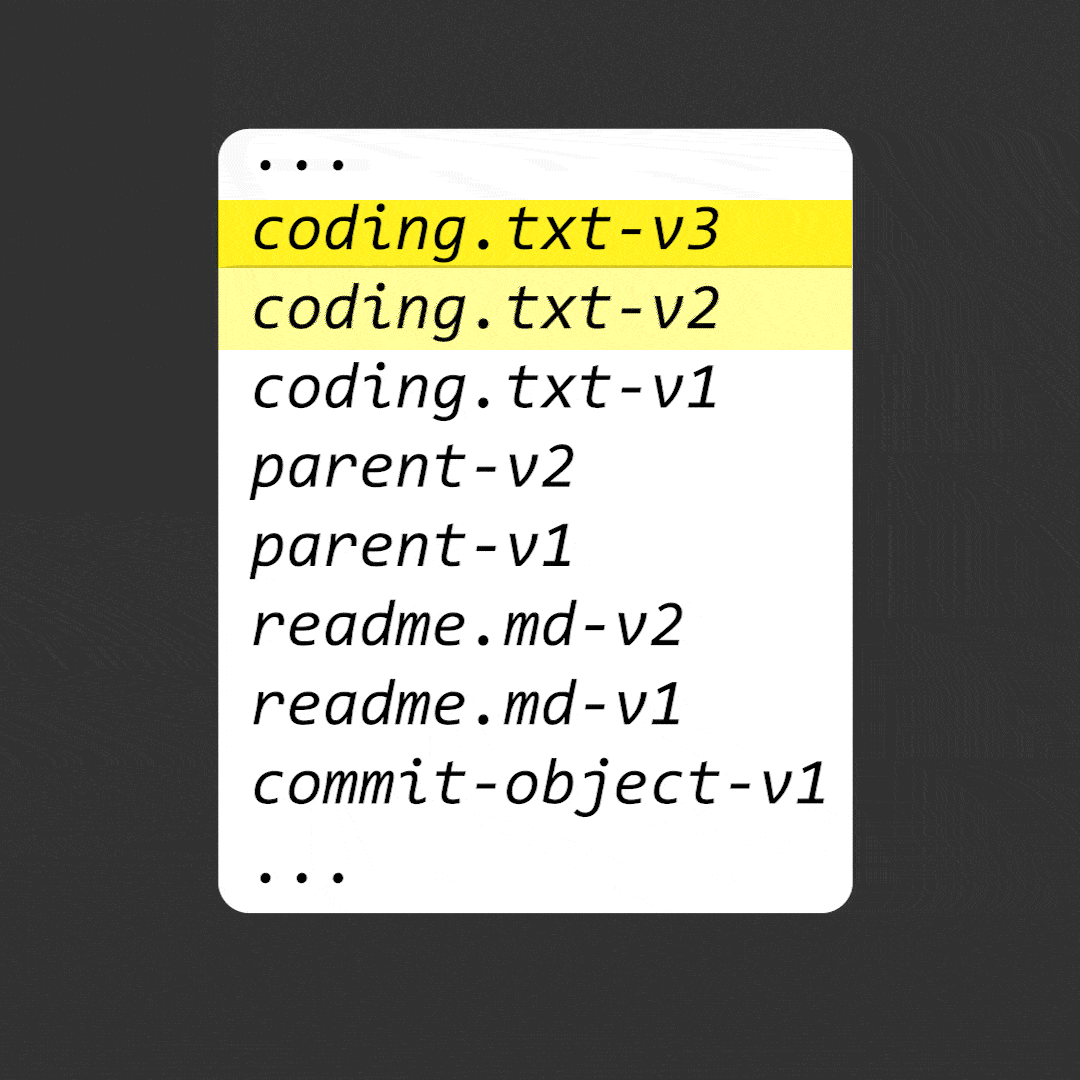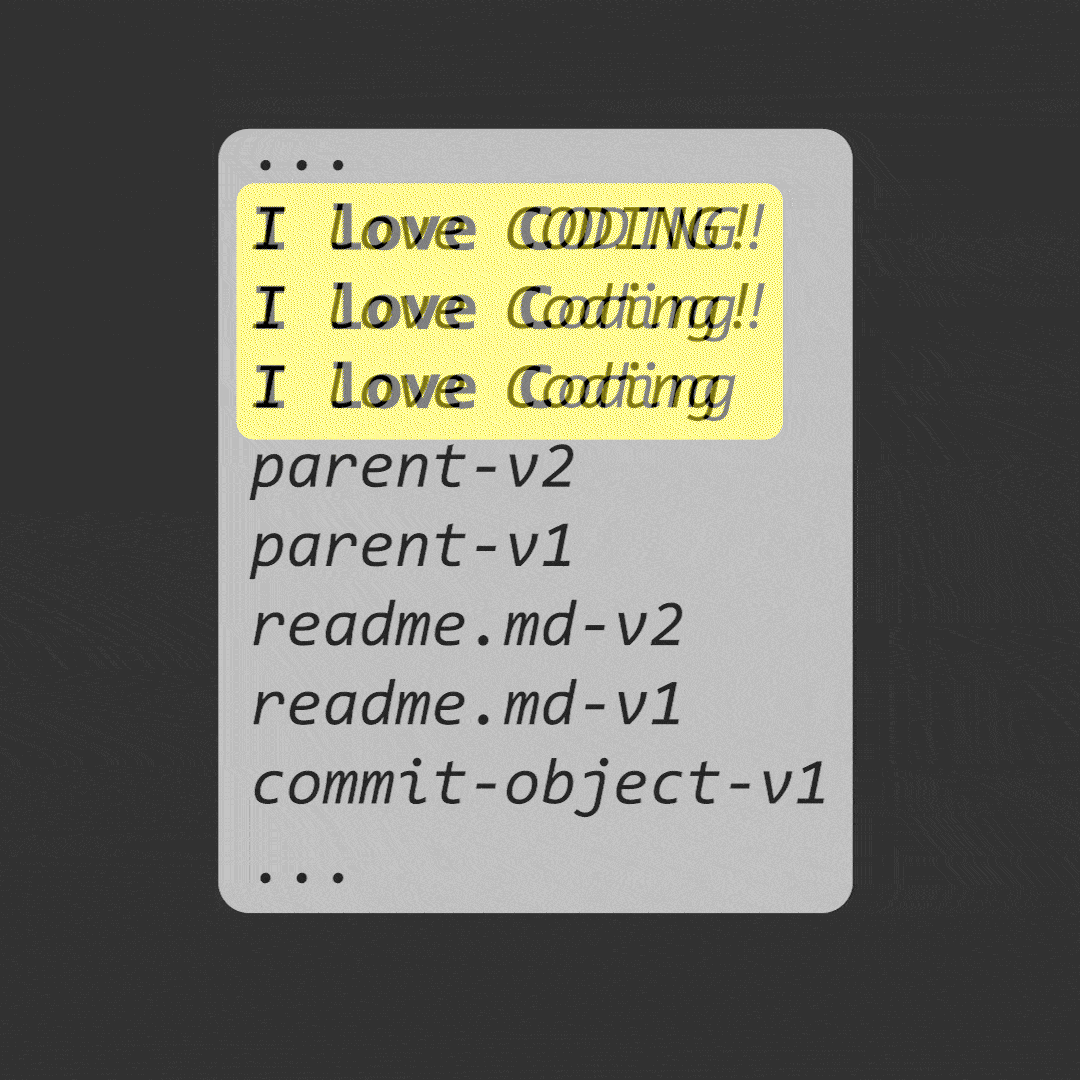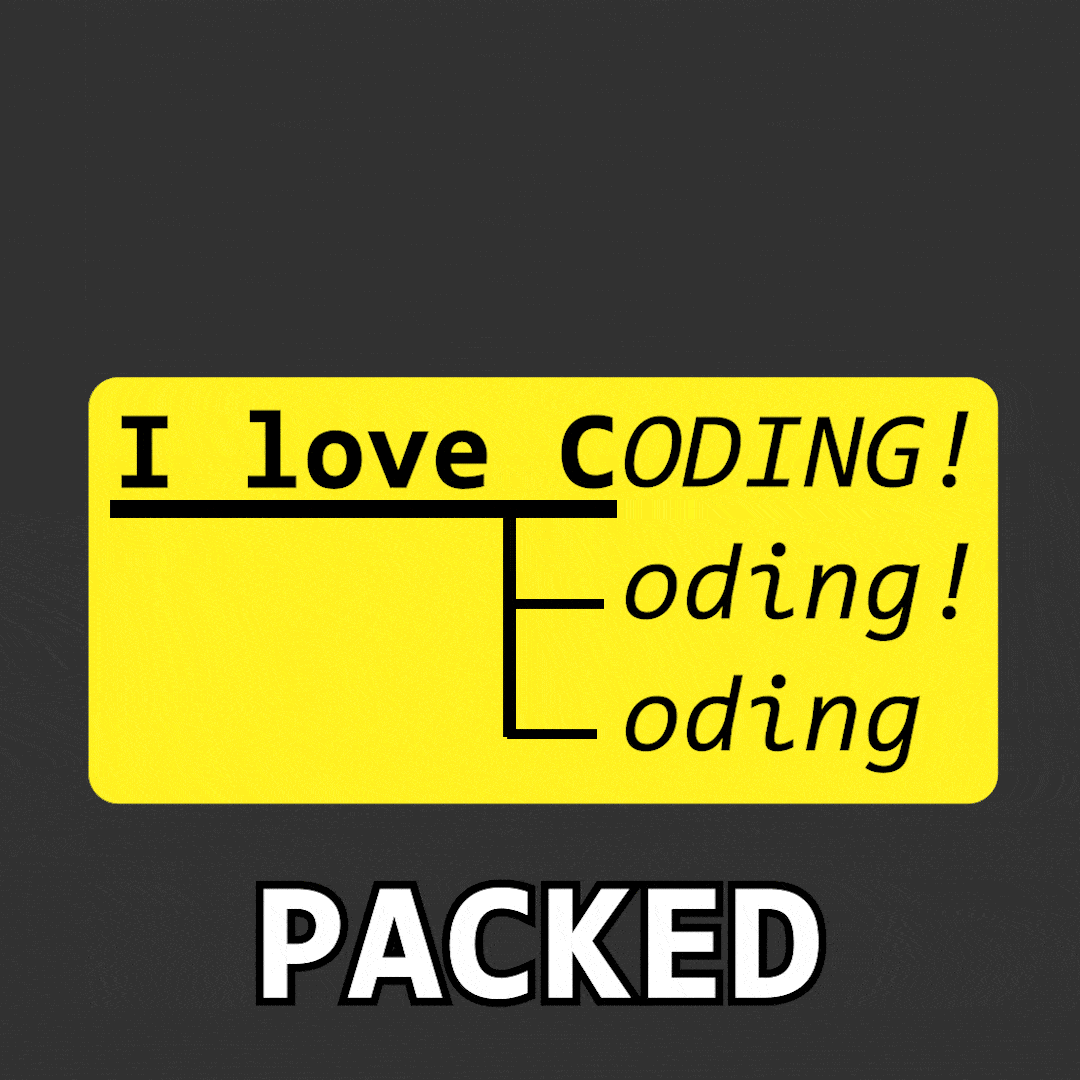
Git has a specific feature for this: Pack Files. They are created using the underlying algorithm.
- Run over file objects by their name.
- Find deltas between objects within a window (currently set to 10).
- If the delta savings are significant, create a pack file.
- Store an entry with the base content in the pack file, and then create child entries pointing to this entry.
4. WHEN DOES GIT COMPRESS FILES
Compressing files is expensive. Constantly running compression on large code bases would waste CPU.
Instead, files are usually compressed when transferring over the network. Hence, we save network transfer costs when necessary while saving CPU time!
5. CONCLUSION
Algorithms based on hashing, compression, and information theory are crucial to Git's success. They work under the hood to provide software developers with a seamless, performant experience.
The next time you run git push or git pull, you know what's happening in the background!
If you want to know more about real-world applications of algorithms, try our system design course at InterviewReady.
Cheers!
References:
Tidbits:
- If the File ID and SHA-1 hash don't match, Git detects file corruption!
- Rename or move operations do not trigger a file copy!
- You can comment on this article to create a new version, that is also managed by Git!