
Here is one reason why NoSQL (usually) runs faster than SQL databases.
Fundamentally, database performance depends on two things: Read speeds and write speeds.
Most applications are read-heavy. This means the faster you read data, the happier your user is.
And therein lies the rub.
1. SQL INDEXES
Database Indexes depend on access patterns. Access patterns are ways in which you query and sort your data.
Knowing this, it makes sense to sort the data beforehand and use Binary Search to search through ranges quickly.
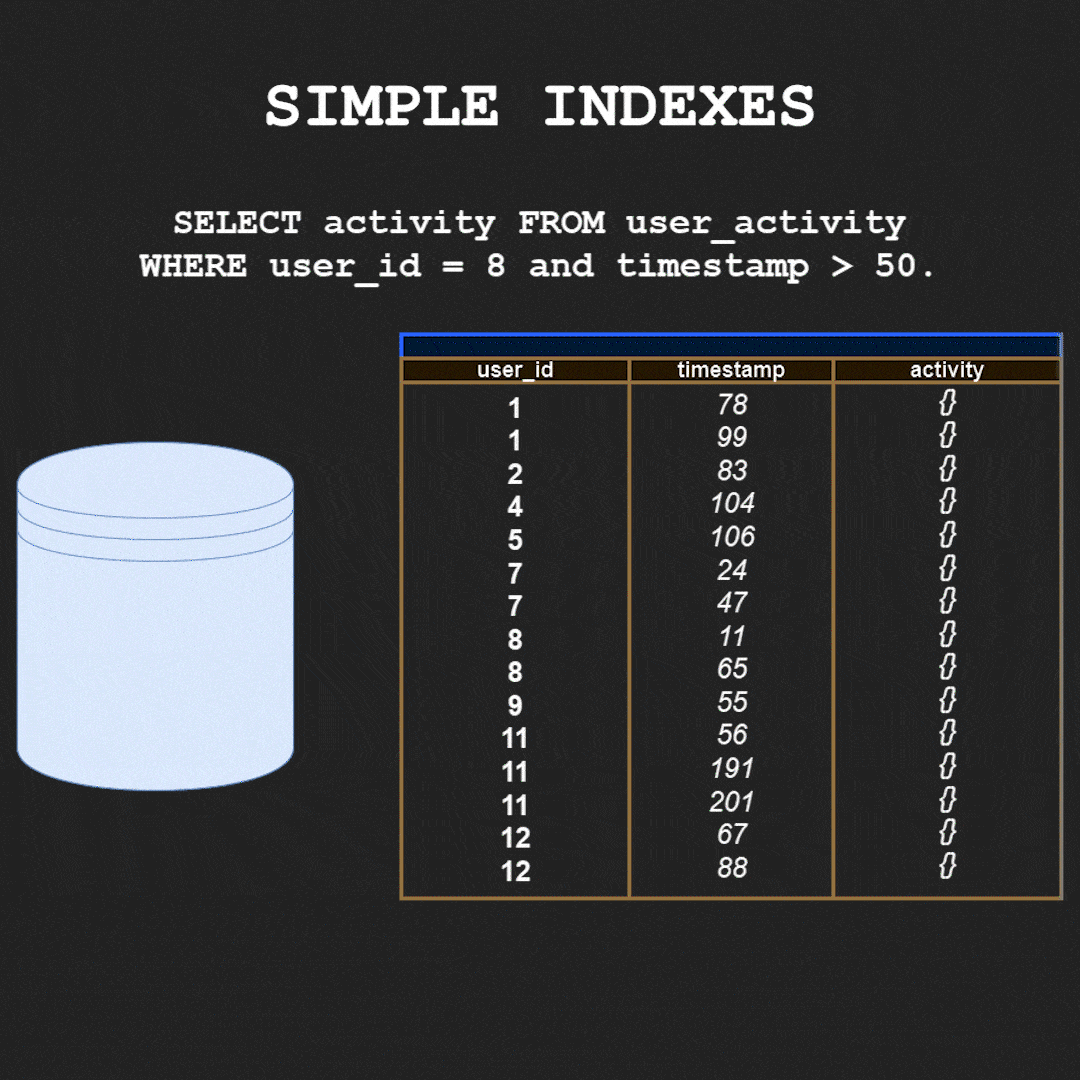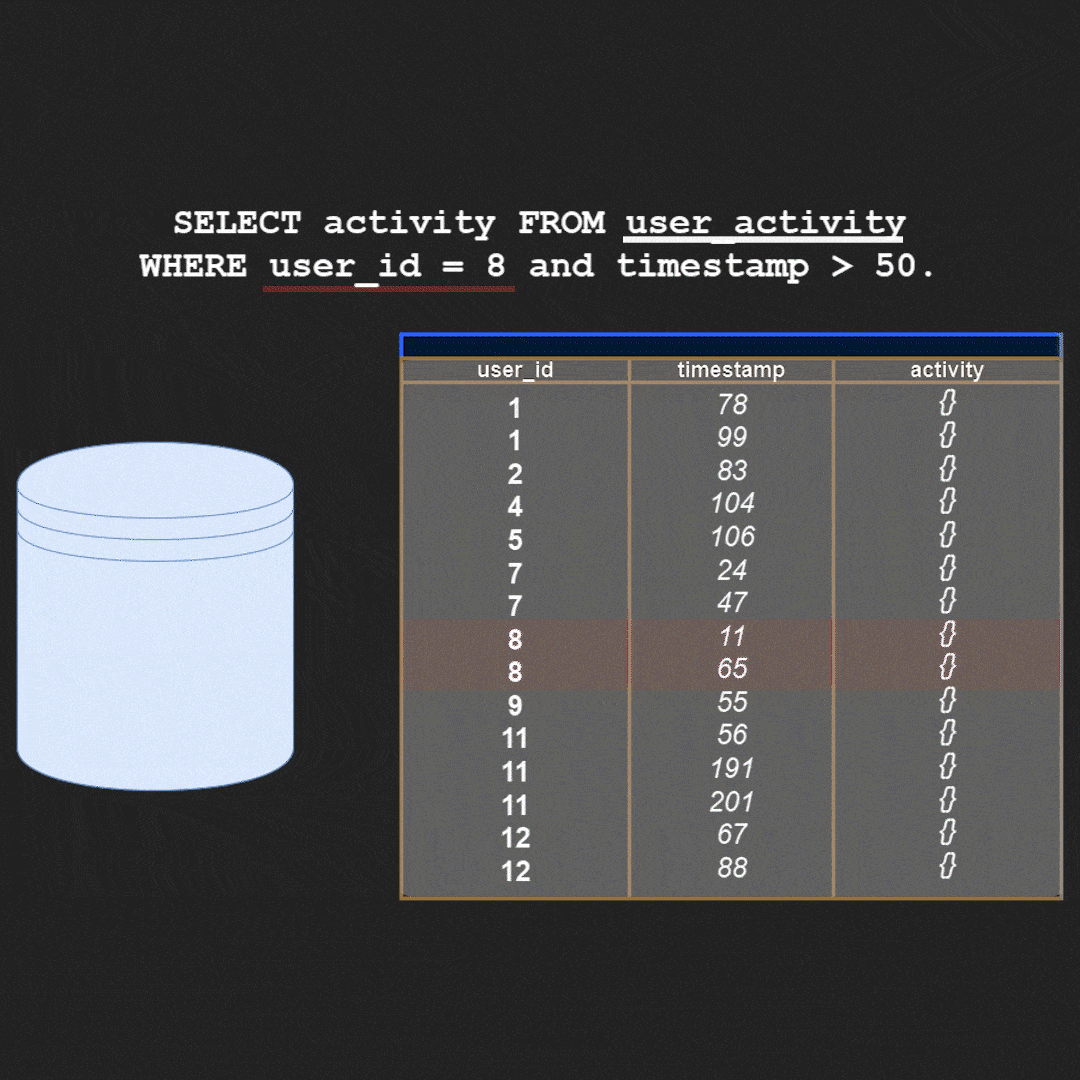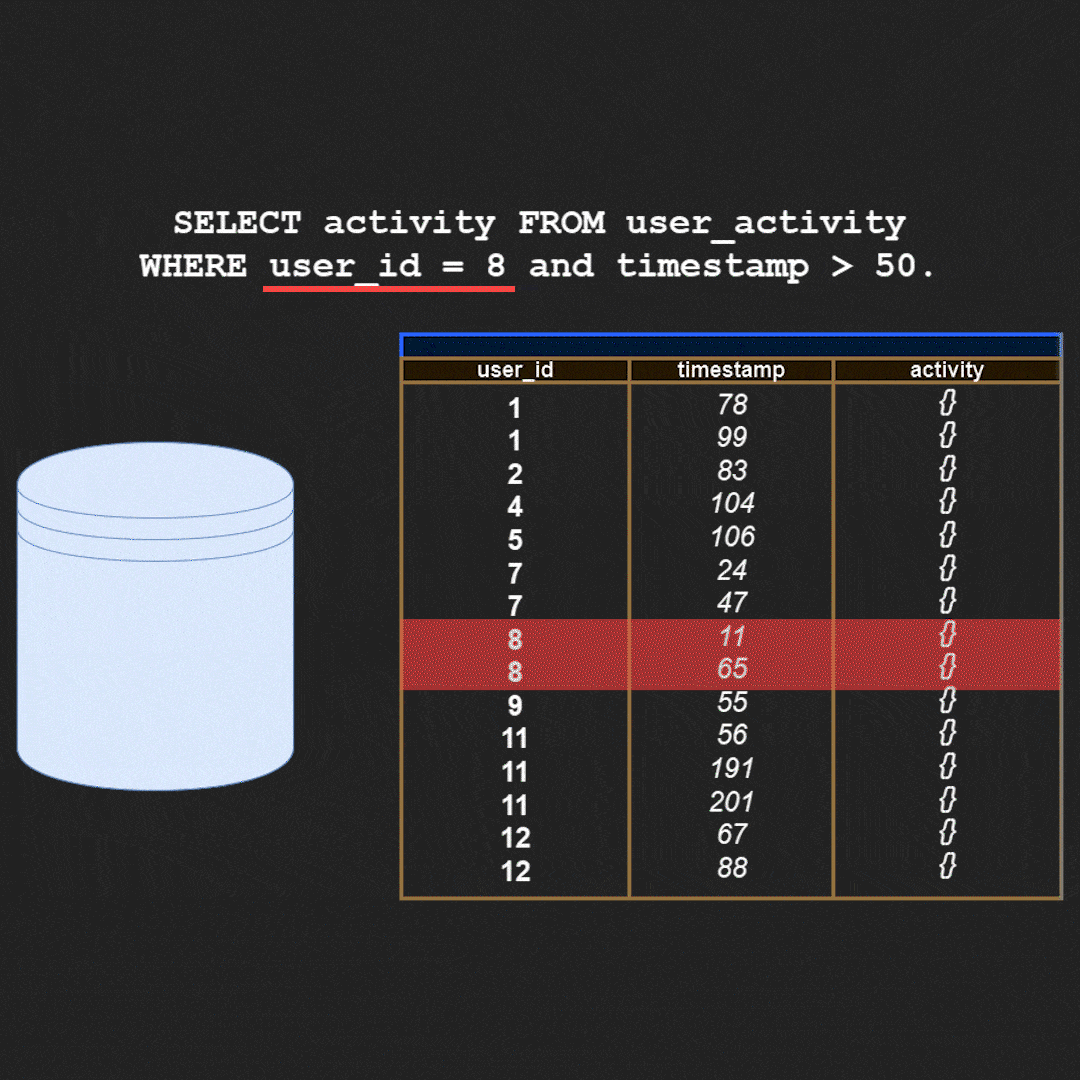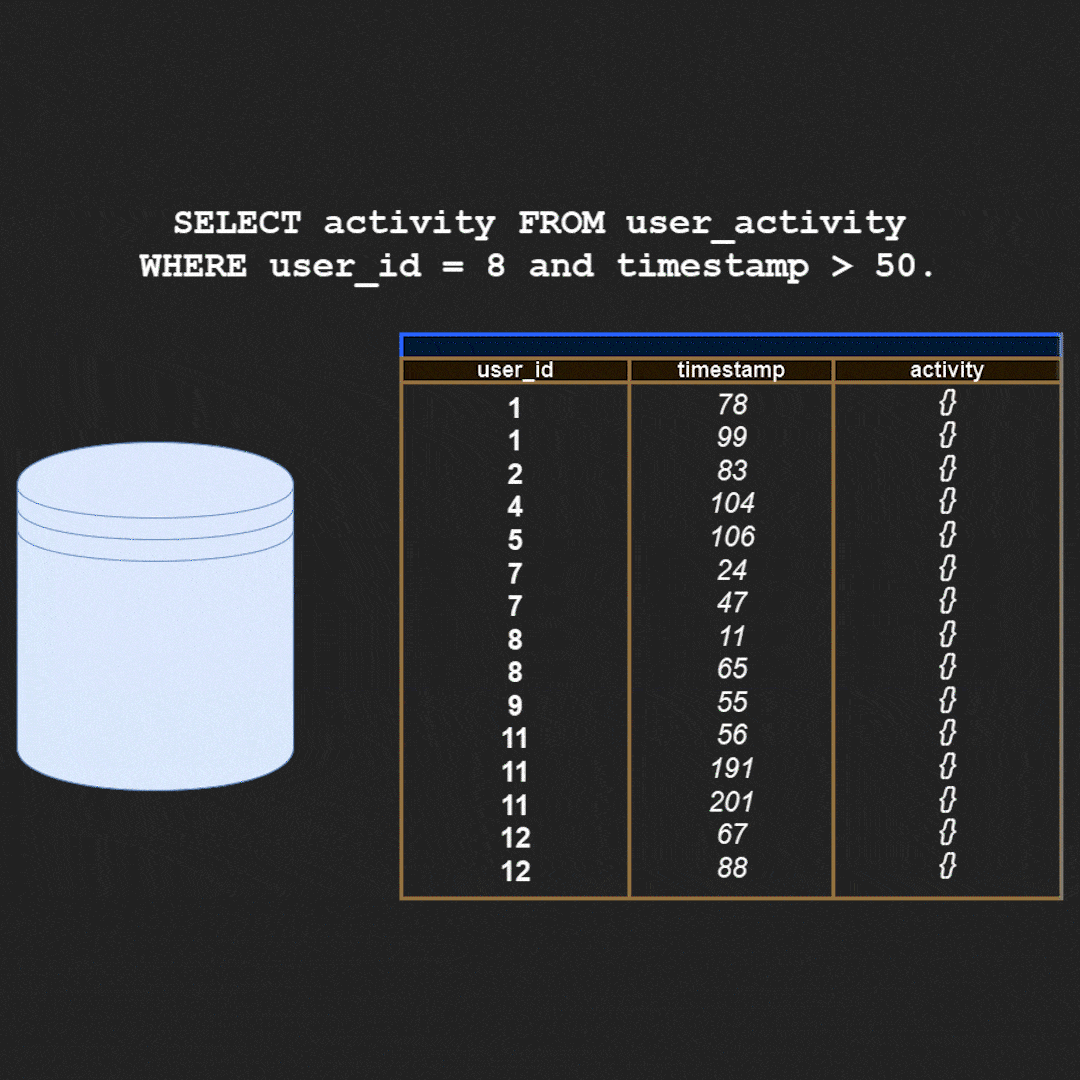
1. SQL Indexes using B-trees, single index
The advantage of this approach is its simplicity. Its drawback is that we may use only one index per query.
Even if we create indexes on user_id and *timestamp, only one can be used at a time. This is because of the binary search algorithm, which can traverse on a single "key" field.
For very large data sets, this approach is slow.
2. NOSQL INDEXES
NoSQL databases are built for scale (This is a fancy way to say that adding nodes to NoSQL database clusters is easy).
As our data set scales, we split tables and load balance them into different nodes.

2. NoSQL indexes using partition and sort keys
But adding nodes complicates our design: We can no longer run a binary search on a single database table. We would have to run the query on every related node, aggregate the results, and return a response.
We can turn this drawback into an advantage.
Instead of naively splitting tables, we partition the data into ranges. Every node serves a range of user_id keys. This is called the partition key.
Inside each partition, we create an index to sort data by timestamp.
Now, our queries can jump to the relevant partition and apply binary search on the timestamp. This approach is very fast.
3. COMPOSITE INDEXES
A third approach exists for our use case. If our data is mainly accessed on user_id and timestamp, it makes sense to merge the two fields.
This helps us run a binary search on the merged field (the algorithm expects a uniform sorted space, the number of dimensions of this space does not matter).
For example, the search for user "8" and timestamp > 50 would be
Select activity from user_activity where composite_key > "8_50";

3. Composite key indexes for fast search
This approach is efficient. It is also easy to implement and does not require partitioning data.
However, you would still need to aggregate across nodes for distributed databases. And this approach is not flexible (the index creation logic depends entirely on the access pattern).
Conclusion
Depending on your use case, you could index your data using either of the three approaches listed above. Remember that your choice should consider the following:
- Access Patterns
- Update Patterns
- Access vs. Update Frequency
Database indexing plays a vital role in systems design. If you want to know more about it, check out our chapter on SQL vs. NOSQL here.
Cheers!