
This series dives into concurrency patterns useful for senior engineers. You can read the first two blogs below:
In this iteration, we explain a design pattern called Request Hedging. Systems like Amazon DynamoDB and Google Zanzibar use this technique to reduce the risk of thundering herds.
Let's dive in!
The problem with "popular" objects

(i) Breakdown of submissions by question.
We launched our System Design Judge three weeks ago. The above graph shows its usage pattern.
The first 12 questions are popular (they take about one hour to complete), after which users take a break from the website.
The chance of a user coming back dips as you move the right. Only serious candidates go through the entire list (a sad reality of online learning websites 🙂).
Looking at this pattern, it makes sense to cache the popular questions in-memory.
- When a GetQuestion request reaches our server, we first check the cache.
- If it doesn't exist, we fetch the question from DB and populate the cache.
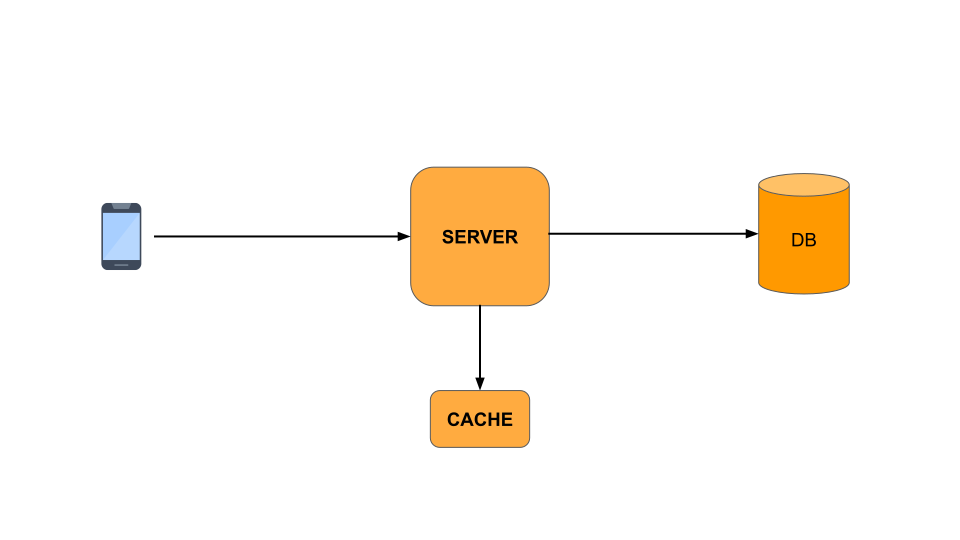
(ii) A single request leads to one DB call and cache population.
What happens if the question is very popular? Multiple requests hit the cache simultaneously.
Since the cache isn't populated yet, both requests fire a DB query!
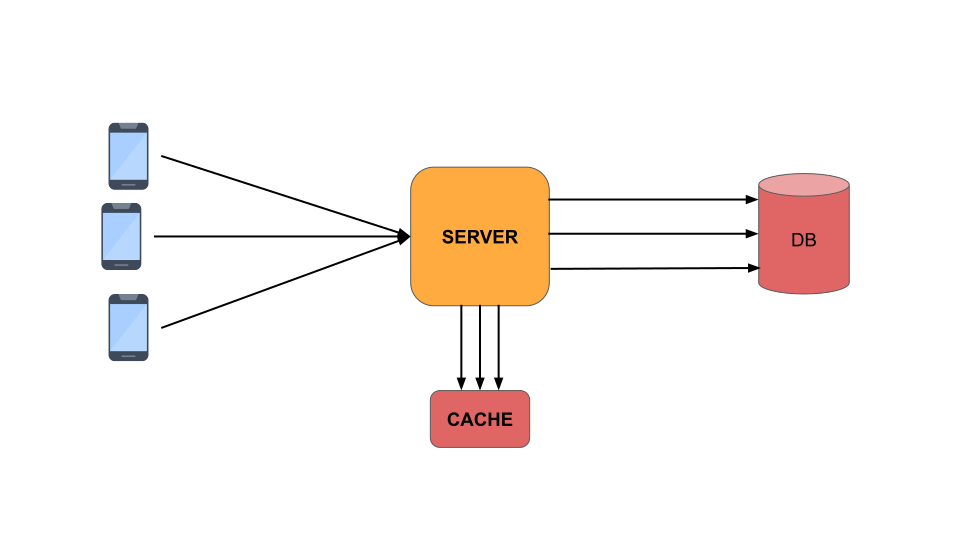
(iii) Concurrent requests lead to wasteful DB calls and cache overwrites.
To avoid this problem, we use a technique called Request Collapsing.
- The first read request acquires a lock.
- All subsequent requests are made to wait on this lock.
- Once the DB call returns and populates the cache, the lock is opened.
- All dependent requests read the result from the cache.
In this way, the pressure on our DB is regulated. When a popular object is requested by multiple clients, instead of making hundreds of DB calls, we make a single call and return the DB response to all clients.
To read more about Request Collapsing, go to Concurrency Patterns for Senior Engineers: Part I.
The fly in the ointment
What happens if a DB call fails?
All requests waiting on that call are affected. These requests will be retried, leading to a spike in DB queries.
Thus a single failed call would lead to a thundering herd of requests from clients.

(iv) Reddit is famous for its "Hug of Death" thundering herd, where lesser-known websites may become unexpectedly popular, leading to massive traffic
Our solution is to choose a middle path. Sending a single request is a single point of failure, leading to high latency and poor user experience. Sending all requests is wasteful and will potentially overload our DB.
So instead we send two duplicate requests. The first successful response is used to answer all dependent requests.
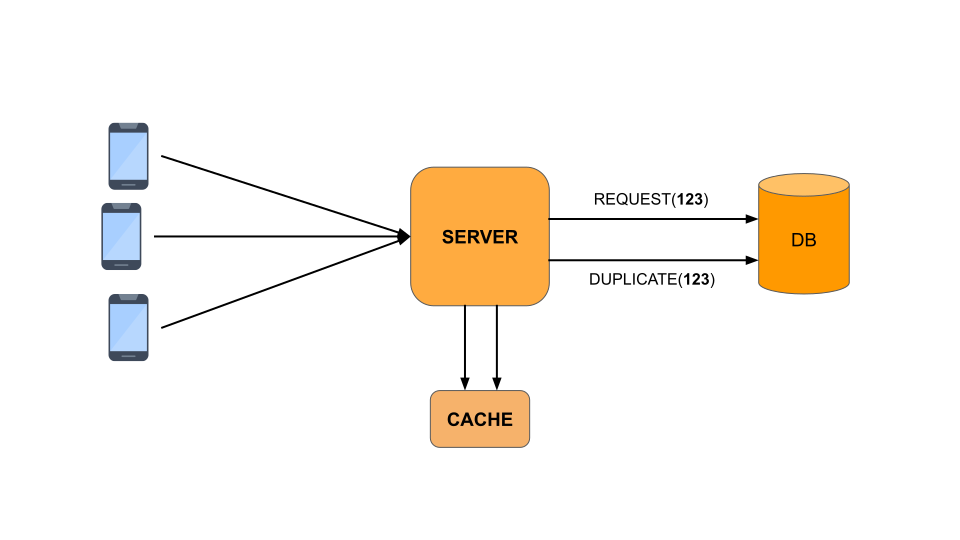
(v) Request Hedging with multiple DB calls.
This technique of hedging our bets by hitting multiple DB replicas with the same request is called Request Hedging.
End result
We decided not to use request hedging in our caches.
At our scale, the added complexity of managing multiple simultaneous requests doesn't make sense. Request collapsing is easy for us to test, but request hedging isn't.
However, both Amazon and Google found this technique useful.
- Amazon uses it to manage massive incoming traffic in its database called DynamoDB.
- Google uses request hedging in its authorization service called Zanzibar. When a popular document is accessed, Google fires multiple requests to quickly populate it's cache.
Amazing engineering. We hope that we too face such scaling challenges soon 😛
If you want to learn more about software engineering and system design, try our detailed System Design Course.
Cheers!