
If you haven't already, check out Part I of "Concurrency Patterns for Senior Engineers".
This blog is continuation of the series: A case study of our notification system.
We will discuss the challenges with large email lists, the solutions we considered for broadcasting emails and the solution which works best for us!
Case Study: Broadcasting emails to 80000 users
Adding a video lesson is considered a course update at InterviewReady. We must notify our users of course updates through email within 24 hours.
The following is a heatmap of course updates for "System Design Simplified" in 2023.

(i) Course update heatmap for InterviewReady till April 2023. Chapter additions cause large spikes.
Each course update is picked by a cron job on the server. This job runs every 30 minutes and performs the following actions:
- If the latest course update was less than 30 minutes ago, exit.
- Else, create an email with all course updates that haven't been broadcast.
- Send this email to all customers.
At the point of writing, InterviewReady has more than 80,000 registered users.
If we send emails immediately to all users together, we will generate many emails in a very short period.
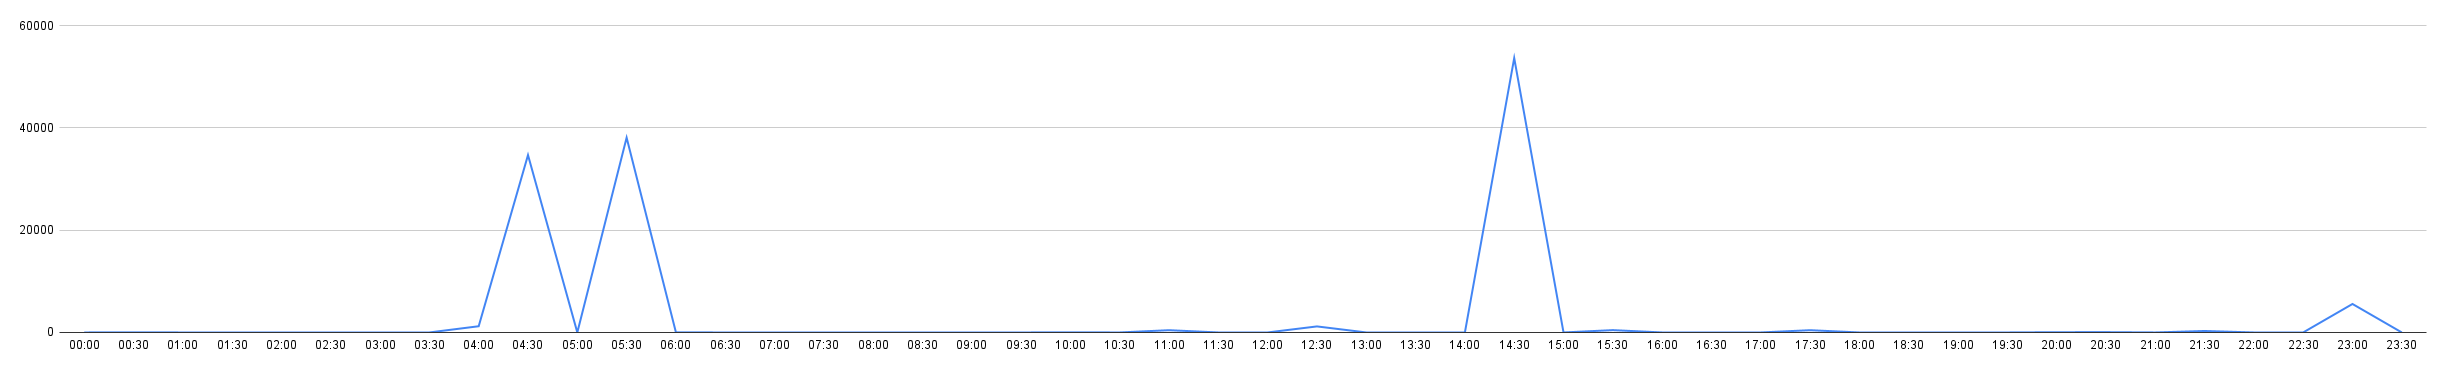
(ii) Sending emails immediately after content updates lead to spikey load.
One way to handle this spike is provisioning servers. Since we are a cost-sensitive startup, we only want to provision servers when necessary.
Q. How do we send emails within 24 hours with the minimum number of servers?
Option 1: Offline Exact Partitioning
Split the original batch into 48 smaller batches. Run each batch at an interval of 30 minutes. The new load graph looks like this:

(iii) Total time taken to complete: 48 * 30 minutes = 24 hours. Note that peak load is now 2000 instead of 60000.
We provision servers as needed to meet peak traffic of 180k / 48 ~= 1666 users.
This is optimal.
Option 2: Real-time Partitioning
The algorithm is described in detail here.
The idea is simple: Run a cron job every half hour. This splits the day into 24 / 0.5 = 48 intervals.
This means you can number the intervals from 0 to 47. Let that be the INTERVAL_ID.
At each interval, find the users with USER_ID % 48 = INTERVAL_ID.
If USER_ID is uniformly distributed, we can assume that each interval will pick about 80k / 48 users ~= 1666 users.
This is also optimal!
Real-life considerations:
Out of the above two options, which one would you choose? Here are some things to consider:
- What happens to users who enroll after partitions are fixed?
- Provisioning a server costs us money, even if it doesn't run at 100% capacity.
With these considerations in mind, we chose option 1!
This simple, no-nonsense algorithm helps us keep costs low with predictable outcomes. We can also resize partitions based on current capacity, as shown in the below diagram.

(iv) Fixed-sized partitioning is ideal for us. We utilise two machines fully before downgrading to one to save costs.
Note that, unlike earlier, we now run servers at 100%.
At any point, if REMAINING_LOAD / SERVER_CAPACITY < NUMBER_OF_SERVERS, we decommission a server.
This let us get rid of servers quickly, further cutting costs.
Final Thoughts:
A basic partitioning algorithm satisfied our needs. This algorithm was easy to code, debug and scale.
P.S. Our product manager is asking us to send update emails to the most active users first. We have been asked to consider currently online users, which makes things tricky.
How would you go about implementing this?
See you in the next part of "Concurrency Patterns for Senior Engineers"!