
Before we discuss the requirements of our cache, let us discuss
What is a cache?
A cache is temporary storage that stores a part of our database in memory.
It is much faster to get the data from the in-memory storage, so it reduces the response time. Also, it reduces the load on the database because if the data is present in the cache it does not send requests to the database.
There are many types of cache, but the most commonly used is the Key-Value pair cache.
Core requirements for our cache
-
Deleting data
There are 2 cases when we must delete data from our cache:
-
Data has expired If the data is in the cache for a long period and it is not begin updated then it might have expired and should be deleted. So we need to set expiry time (also known as TTL ) for the key-value pairs. If a key-value pair exceeds this expiry time then it is deleted.
-
Cache storage is full and we need to insert new data If our cache storage is full and we need to replace the old data with the new one. There are many replacement algorithms like LRU (Least Recently Used) and LFU (Least Frequently Used) which decide which key-value pair must be replaced.
-
-
Writing data
2 policies are used to write data in a cache
-
Write Back Policy In the Write-Back policy, we keep the values in the cache and then flush all the values into the database at once.
-
This prevents us from hammering the database with requests, so it is more efficient.
-
However, it is riskier to use. For example, the updated value is stored in the cache but before the cache could flush it to the database, there is power loss. Now that data is lost.
-
In the distributed cache, the updated value is stored in one of the caches. If the server requests the data from another cache then it will receive stale data.
-
-
Write Through Policy In Write-Through Policy the value is updated in the cache and then it makes a synchronous call to the database. So it updates both the cache and database at once.
-
It is less efficient compared to the Write-Back policy.
-
Since the data is written on the database and cache simultaneously there is no risk of data loss.
-
When the database is updated it sends the updated value to all the cache, so users won't get stale data.
-
-
-
Read your own Write policy
Before discussing this policy let us consider a situation.
Suppose a user sends a request
update value of the key(A) to X. While the write operations are being processed, the user sends aread(A)` request. Since the value of A is still not updated user will get stale data.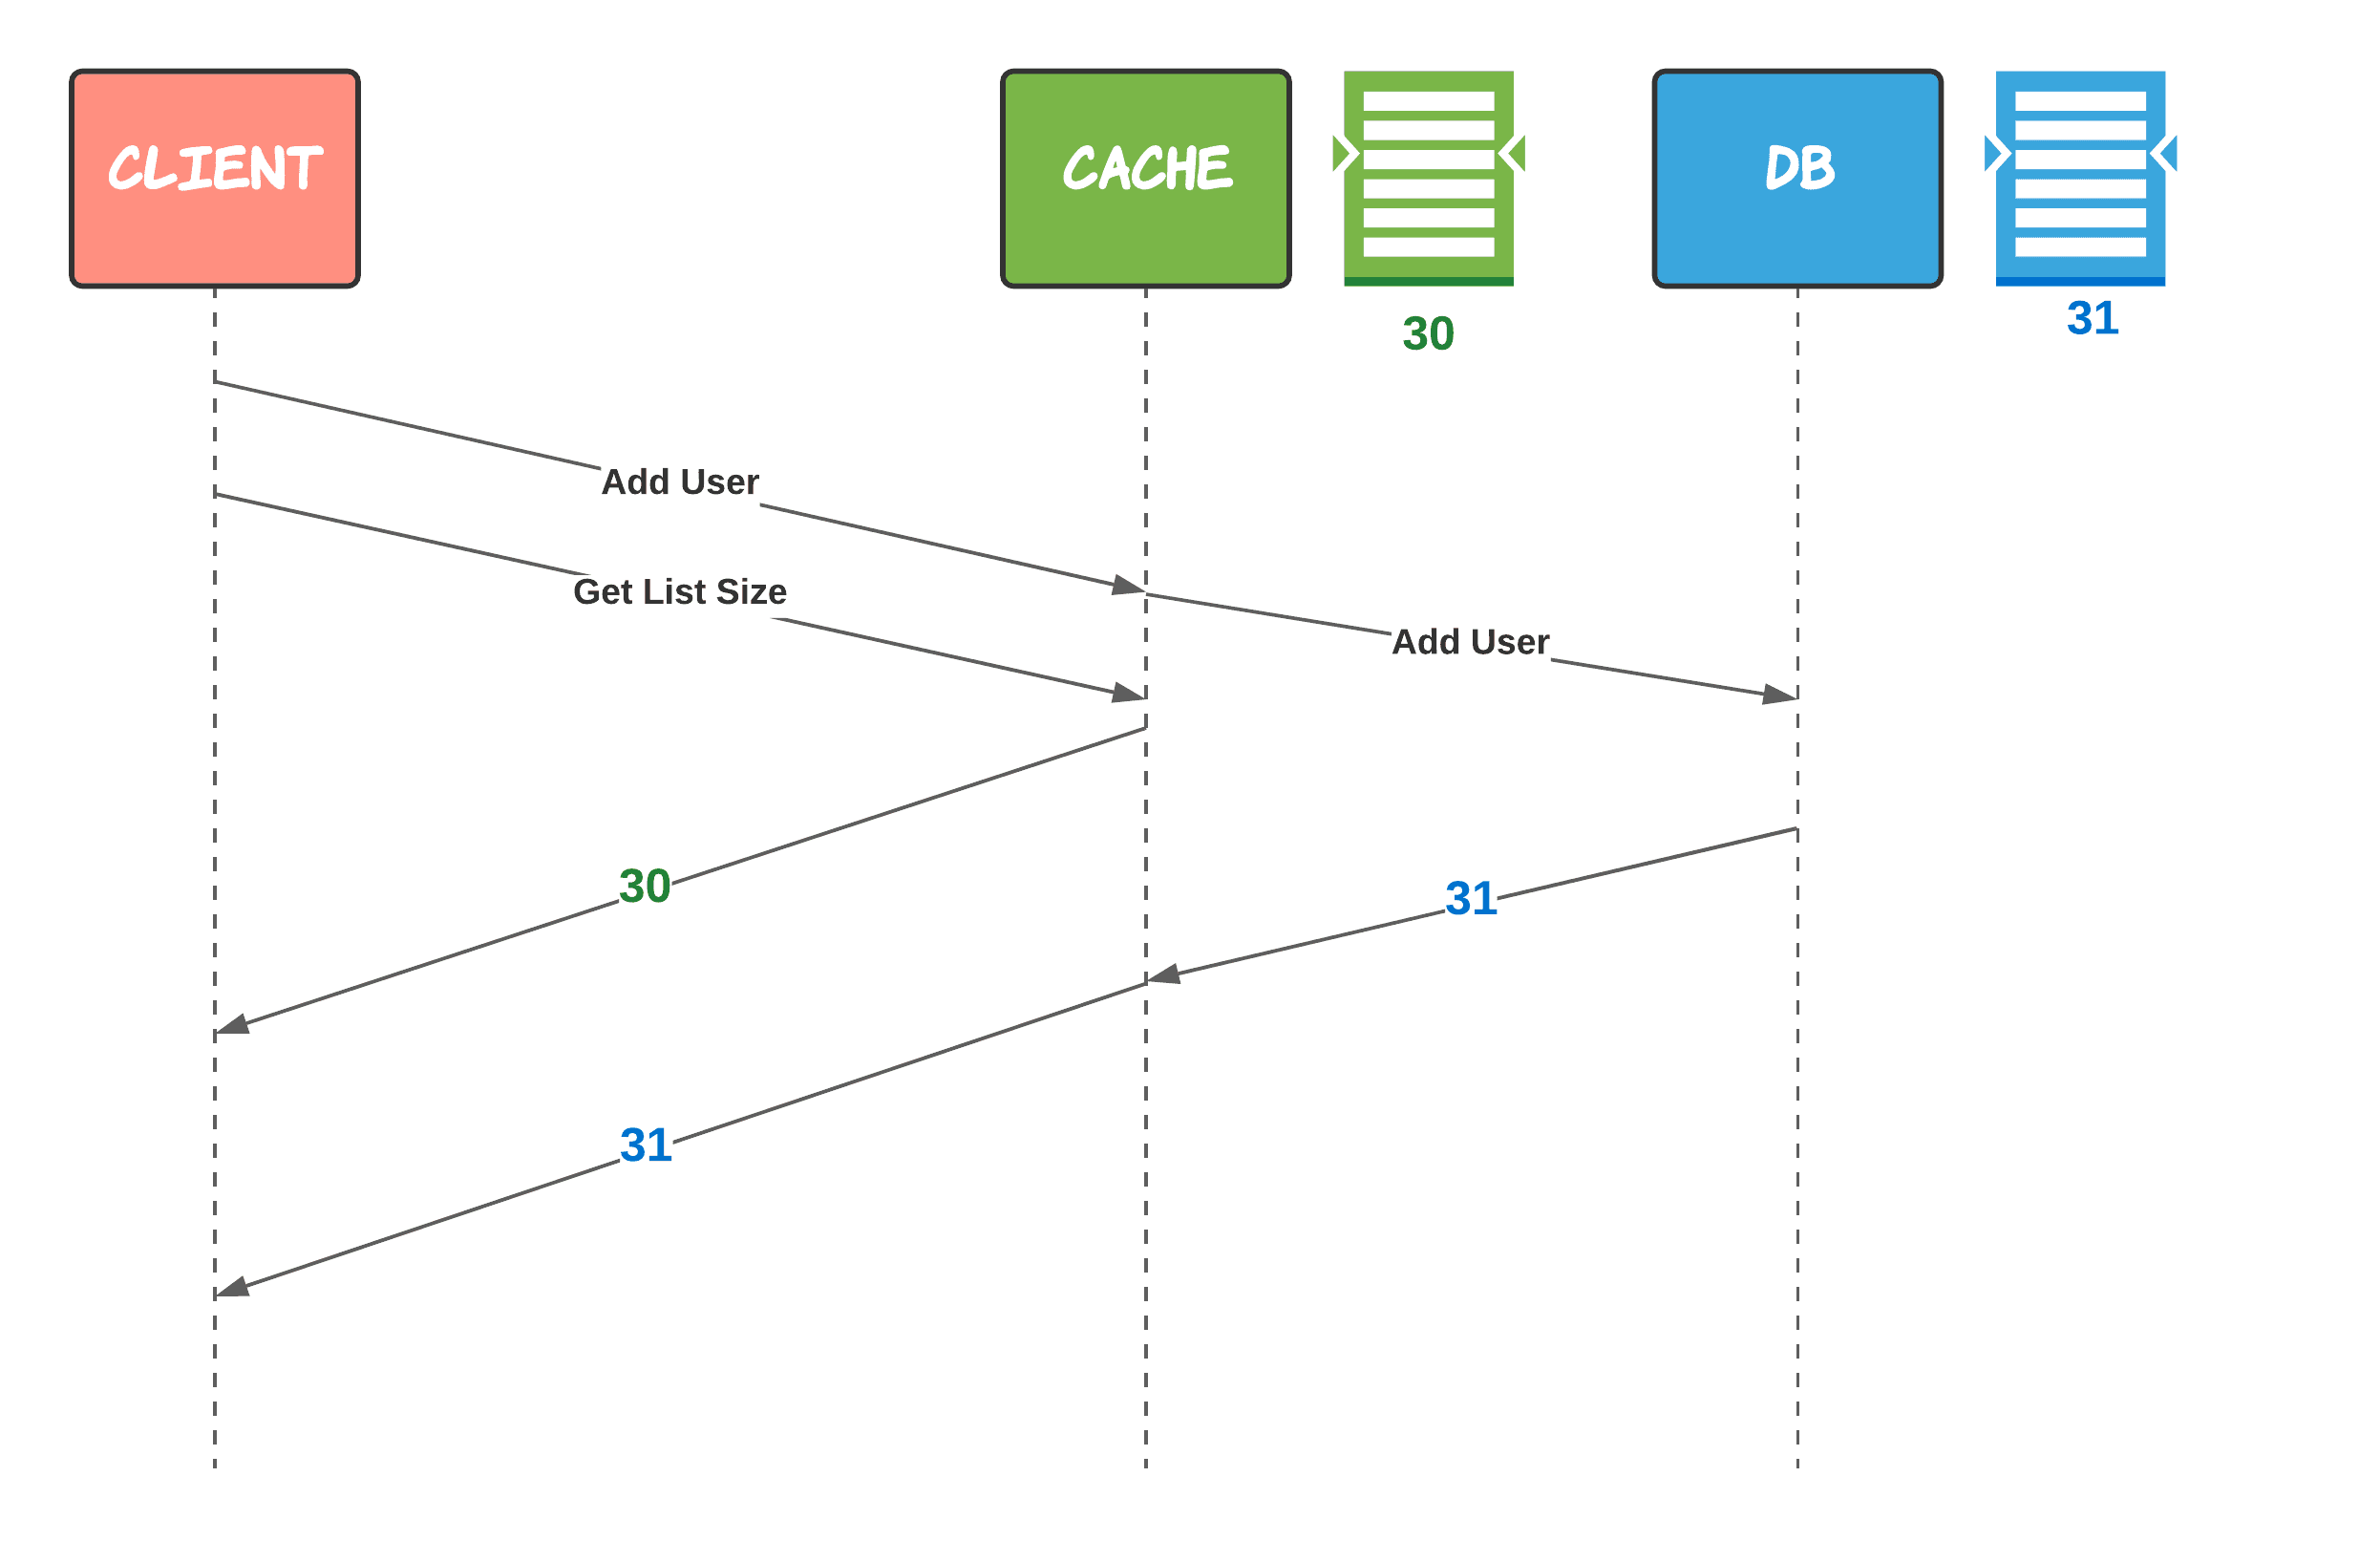
After the Add user request there should be 31 users but since writing to the database is slow it still reads 30 users
So we have to implement a policy such that users will always read the value that was last written.
-
Request Collapsing
If there are multiple requests for the same key then we condense all the requests into one request, make the query and send the response to all the clients.
-
Hot Loading (Pre fetching)
We pre-fetch the data (when the system is starting up) and store it in the cache before they are needed or there is a read miss. So there are fewer read misses and less number of miss penalties which improves response time.
-
Event Log
Anytime there is a new write, update, delete, or any event we want to send the log to the database or analytics engine. These logs are used
-
Asynchronous processing
Asynchronous processing prevents the client from blocking the threads of the cache and improves the performance of the cache.
Implementing Asynchronous processing
Issues with synchronous processing
- Thread Blocking When a client sends a request to the cache then there is a connection between the socket of the client and the socket of the cache. Each socket of cache is assigned one thread and there is a limited number of threads. In synchronous processing, client keeps the thread blocked while waiting for a response. Since the number of threads is limited after a certain number of requests all threads are blocked and the cache cannot handle any more requests.
- Head of Line Blocking If initially, all the requests sent by the client require a lot of processing then there are fewer sockets left for the newer request which requires less processing time. So the newer requests have to wait more which increases response time.
To avoid these issues we want our results asynchronously. To implement that we can use programming abstractions. In Java, it is called Future.
Implementing Asynchronous processing with Future Object
A future Object is a container of results. It is a memory address that is blank initially. When the response is ready it is filled in the memory address. Once the memory object knows that the address has been filled it sends the response back to the client. (Future knows that the memory address is filled through a push/pull mechanism).
There is one more memory address known as exception. If there is a failure, an exception address is filled. So the future object is completed either when an exception is filled or the memory address is filled.
Implementing Read your Own Write Policy
There are two ways to implement this policy:
-
Using Locks
When we are updating the data we lock the address of the data. When the data is locked any other client cannot read/write the data. This makes sure that users can read the data after it has been written.
The problem with this approach is that if the client that sets the lock dies then the data cannot be accessed by other users for an indefinite amount of time. Although there are multiple ways to solve this issue like setting an expiration time on locks or making sure the client unlocks the address before it dies.
-
Ordering using threads assignment
- In our operating system we have a thread pool with multiple threads. Each process is assigned to a thread.
-
It is important to note that a thread executes the processes in the order in which they were assigned (sequentially). There is no concurrency in a thread.
E.g., if process A was assigned to thread T1 first followed by process B then T1 first processes A and then B.
-
To implement ordering operations on a particular key must be assigned to a particular thread. We implement this using hashing.
e.g, Process on Key
Ais always assigned to Thread T1 and Process on KeyBis always assigned to Thread T2.
But how does this solve our problem?
Let us consider a case where we have 2 requests
The first request - Write
Zto keyAThe second request - Read value ofASo 1st and 2nd requests are assigned to thread T1 in order. T1 first updates the value and then reads the value.
From this example, it is clear that we will always read the value that was last written.
Understanding Thread assignment in detail
-
We have a task scheduler that uses hashing to assign a key to the threads.
 The same key is always assigned to the same thread
-
An OS Task Scheduler takes the total execution time and breaks it into pieces. It then assigns each piece to a thread. It prevents the threads from starvation. If one thread is waiting then it can move on to the next thread.
-
Consider the below example of a single-core system. It is easy to see that the processes are executed sequentially.

Here the processes for key A are assigned to thread 1.
-
Even for the multi-core system it ensures that the processes are executed sequentially.
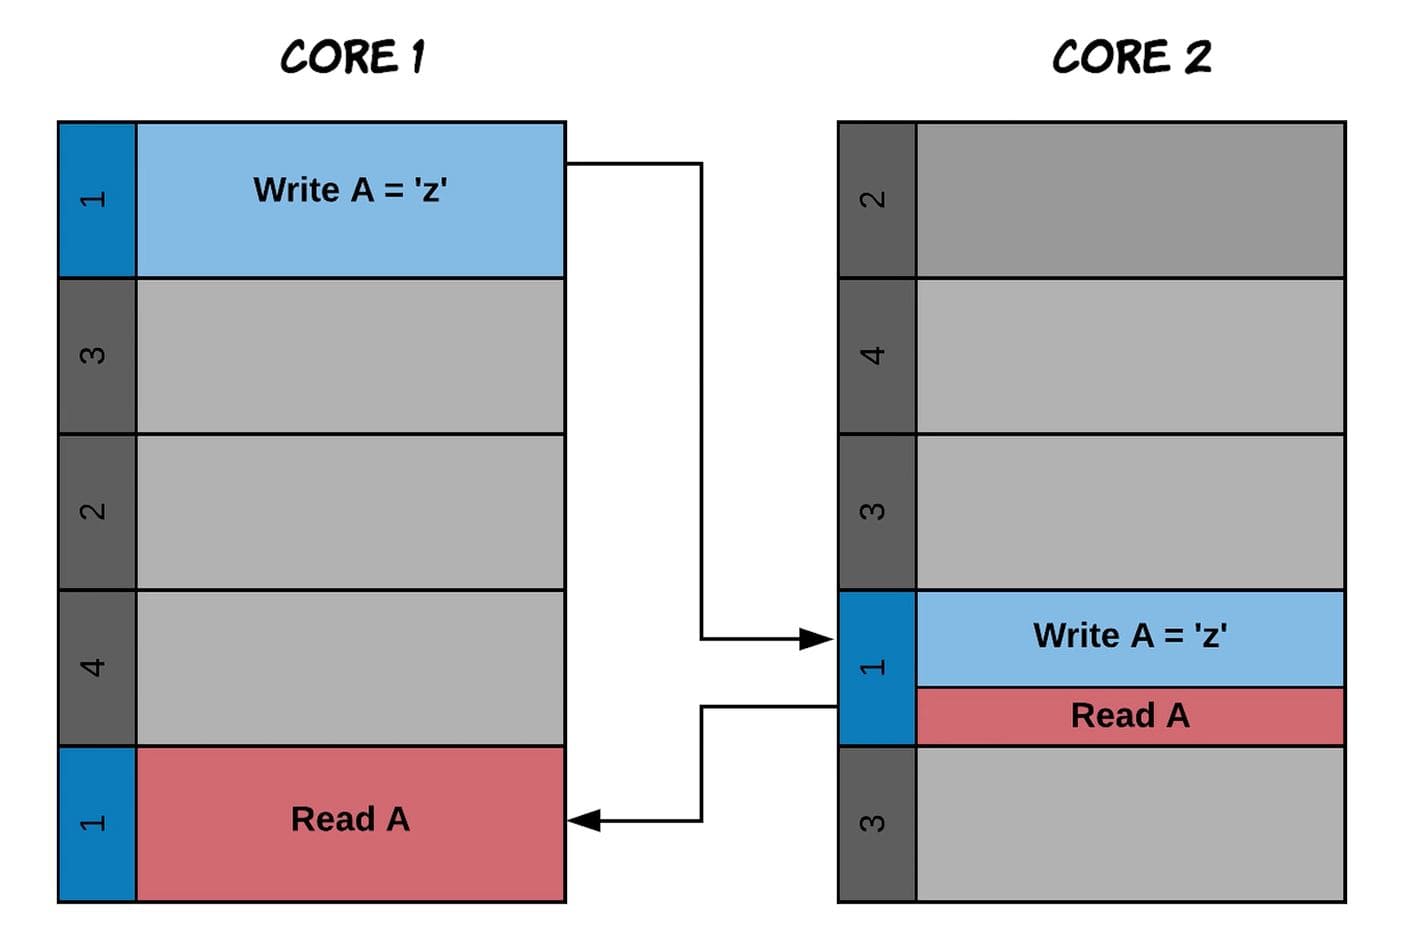
- Now let's consider a case where the task for the same key is assigned to different threads. From the below example it is clear that it would violate the read your write policy.
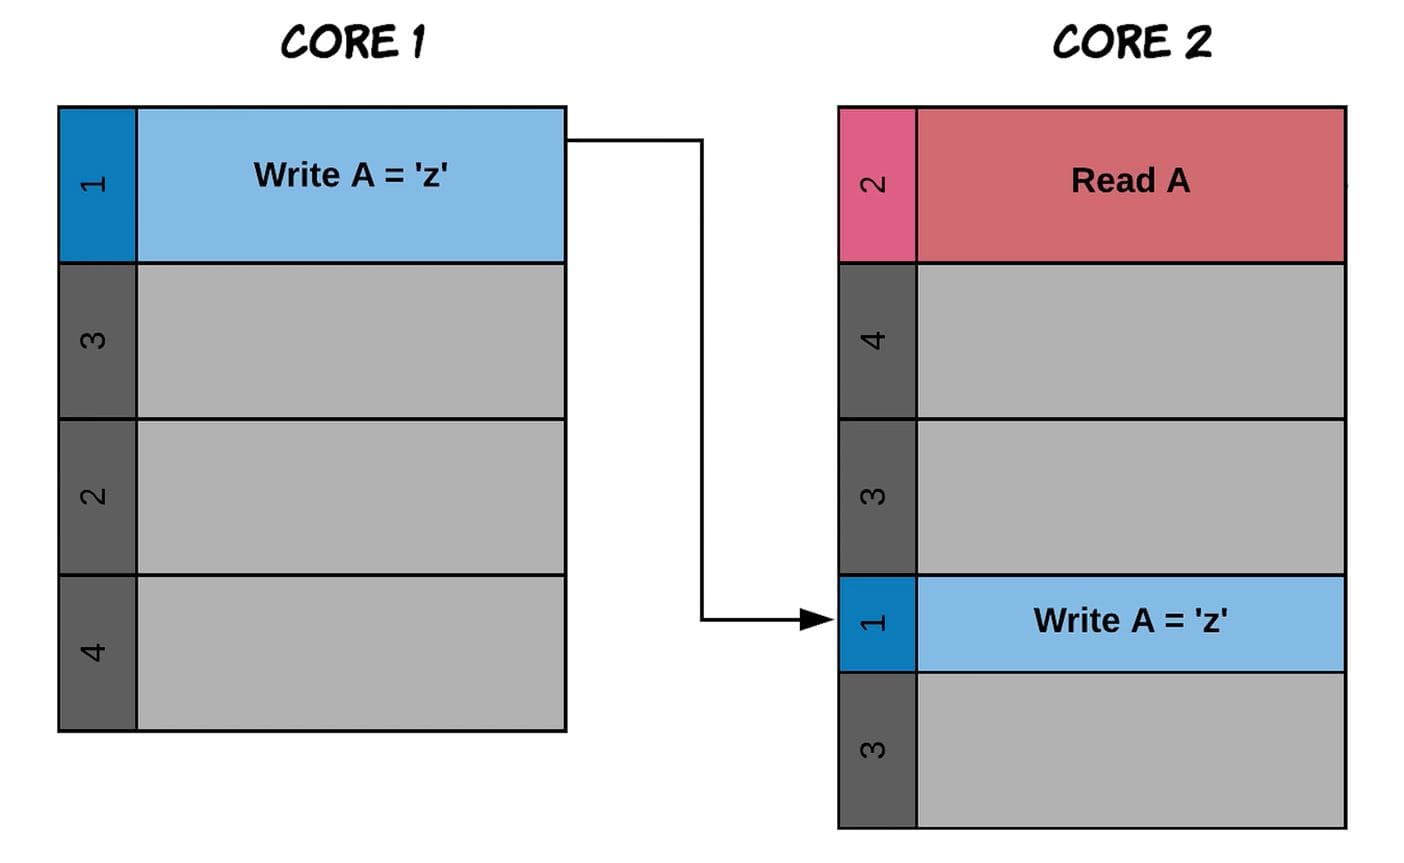
Read of A is assigned to Thread 1 and write of A is assigned to Thread 2. So it first executes B (reading the stale value) and then updates A. Therefore it is important to assign processes of a particular key to a particular value.
That's it for now!
You can check out more designs on our video course at InterviewReady.
